Welcome to
the Forum
Engage innovators and practitioners on the edge of technology advancement.



HPE's Mild-to-Wild Rack Tour: From ORv3 to the Cray GX5000
One thing has become clear: agentic AI is not going to run in just one type of data center. It will spread across enterprise server rooms, colocation facilities, national labs, and sovereign clouds. Each of those environments requires a different combination of compute, storage, and networking, and all of that heterogeneity has to fit into the same physical infrastructure. At the center of it is the rack.
I asked the HPE team to walk me through it at OCP Summit. Strolling from an open-standard ORv3 rack to a 400-kilowatt Cray supercomputing rack, we called it the mild-to-wild tour. My guide was Jason Zeiler, a data center infrastructure lead. Our conversation raised an interesting question about the future of AI infrastructure: Who gets to define the rack? And can one vendor support both industry-standard configurations and highly specialized systems?
Why the rack now matters more than ever
For decades, the rack was largely a standardized enclosure: you picked a width, bolted in servers, and moved on. But the power, cooling, and networking demands of AI are changing how operators approach rack design.
It’s not just about floor space either. As HPE noted in The Next Platform, the industry is now wrangling with power densities ranging from roughly 30 kilowatts to as much as 1 megawatt. While liquid cooling already extends across entire racks to manage the heat, AI infrastructure also calls for sufficient network bandwidth and reliable power delivery.
These considerations become more complicated as operators combine different hardware generations and workload types within the same facility. A rack architecture needs to accommodate not only its current equipment, but also the operational demands of future upgrades.
Rack dimensions and component placement influence how much hardware operators can deploy within a given footprint, as well as how they maintain and service those systems. The mild-to-wild tour demonstrated just how significantly these requirements vary depending on workload and deployment environment.
Mild: ORv3 and the open-standard path
Our first stop was an Open Rack Version 3 (ORv3) configuration, an OCP-standard rack with 21-inch rail-to-rail spacing. Jason described it as the next generation of scalable infrastructure, a repeatable design that uses Open Rack Unit (OU) increments and provides a consistent platform for HPE’s next-generation servers.
“Mild,” however, doesn’t mean modest. Jason was clear that HPE is planning for greater rack density.
“If customers want to fully load racks, they’re also going to have proper cooling and power,” he said.
ORv3 supports native liquid-cooling capabilities, power shelves, and multiple voltage ranges to accommodate higher-density deployments. This is a deliberate design decision to support scalability, not simply a lower-power alternative.
HPE’s new ProLiant Gen13 family reflects this flexibility, with four servers designed for two different rack standards. According to HPCwire, the DL585a and DL525 use conventional 19-inch racks, while the XD245 and XD285 support 21-inch ORv3 configurations for AI and high-performance computing (HPC) workloads. Availability is staggered: HPE expects the systems to become available in phases beginning later in 2026. This gives operators a choice between established rack infrastructure and newer OCP configurations as they plan future deployments.
HPE is also adapting HPE Juniper Networking QFX Series switches for ORv3-compliant deployments. As rack density increases, networking equipment must be considered as part of the rack’s total thermal and power budget, alongside compute.
But rack density is only part of the equation. Organizations also need the flexibility to adapt their infrastructure as workloads evolve.
When I asked Jason who this rack is really for, he described enterprise deployments ranging from half a rack to a thousand racks. Many customers aren’t building enormous, homogeneous clusters. Instead, they want to deploy different types of technology over time. That could mean mixing CPUs, GPUs, storage, and networking within a standardized rack architecture, then adding or replacing systems as workloads evolve. ORv3 provides a consistent form factor for that kind of incremental expansion.
Wild: the Cray GX5000
At the other end of the spectrum is the HPE Cray GX5000, a purpose-built supercomputing system designed for extreme compute density. And the difference in scale is staggering.
Where ORv3 uses 21-inch rail-to-rail spacing, the GX5000 uses a purpose-built 900-millimeter-wide compute rack, compared with the 21-inch equipment architecture used by ORv3. Standing beside the cabinet made its scale immediately apparent. The larger form factor accommodates substantially greater power density.
According to The Next Platform the GX5000 supports up to 400 kilowatts per rack, while liquid cooling extends to the compute blades, networking, power supplies, and even the bus bar. Rather than adding cooling capabilities to a standardized rack, HPE designed the GX5000 around a fully liquid-cooled architecture.
The increase in density is particularly striking when compared with the previous-generation Cray EX4000. Compared with the previous-generation HPE Cray Supercomputing EX4000, the GX5000 reduces the compute-rack footprint by 25%, moving from a 1,200-millimeter-wide cabinet to a 900-millimeter-wide rack while supporting up to 400 kilowatts per rack.
Marvell to Acquire Lumentum in $115 Billion AI Optics Deal
With its planned $115 billion acquisition of optical components maker Lumentum, Marvell Technology is positioned to significantly expand its role in the AI infrastructure market.
The all-stock transaction, announced November 2, 2026, consolidates Marvell’s expertise in high-speed interconnects, network switching, and custom AI silicon with Lumentum’s lasers, optical transceivers, and specialized semiconductor manufacturing. As AI infrastructure operators confront increasing bandwidth, power, and connectivity requirements, the companies plan to develop more tightly integrated electrical and optical solutions to support more demanding workloads.
Unanimously approved by both boards, the agreement specifies that Lumentum shareholders will receive 4.5 Marvell shares for each share held, representing approximately $1,132 per share and a 23.9% premium. Upon closing, Marvell shareholders will own roughly two-thirds of the combined company, with Lumentum shareholders holding the remaining third.
Bringing Electrical and Optical Connectivity Under One Roof
Marvell’s acquisition reflects the growing significance of optical interconnects as AI infrastructure scales beyond the practical limits of copper-based connectivity. Larger AI clusters require increasing bandwidth between accelerators, switches, and distributed systems. While copper remains critical for short-distance connections, maintaining signal integrity, managing power consumption, and extending reach become bigger challenges as data rates and connection distances expand.
Marvell and Lumentum intend to address these constraints through closer coordination of electrical and optical technologies.
Marvell contributes capabilities in electrical and optical interconnects, network switching, custom XPUs, XPU-attach silicon, and advanced semiconductor design. Its existing portfolio includes PAM and coherent digital signal processors (DSPs), Ethernet switching, PCIe and CXL technologies, and custom AI accelerators. Lumentum adds high-performance lasers, optical transceivers, optical circuit switching (OCS), and compound semiconductor manufacturing, particularly indium phosphide (InP) technology.
The companies plan to develop integrated connectivity solutions across four AI networking domains: scale-across, scale-out, scale-up, and scale-in. These domains span connections between geographically distributed data centers, communication within data centers and accelerator clusters, and emerging optical links closer to individual processors and packages.
The acquisition could also accelerate development of co-packaged optics and other architectures that place optical connectivity closer to compute silicon, reducing electrical signaling distances and associated power requirements.
Expanding Manufacturing and Market Opportunities
Lumentum’s manufacturing capabilities represent an important component of the acquisition. The company manufactures high-speed and high-power lasers using specialized compound semiconductor processes, potentially giving Marvell greater control over optical component development, production capacity, and integration with its semiconductor designs.
The transaction also builds on Lumentum’s expanding role in AI infrastructure, including its relationship with NVIDIA and investments in InP laser manufacturing.
Marvell estimates that the combined company will address a $550 billion total addressable market. It also expects stronger long-term revenue growth, improved non-GAAP gross and operating margins, and more than $1 billion in annual run-rate cost synergies.
The transaction is expected to close in the first half of 2028, subject to shareholder approvals, regulatory clearances, and customary closing conditions. Marvell Chairman and CEO Matt Murphy will retain both positions. Three Lumentum directors, including CEO Michael Hurlston, will join Marvell’s existing seven-member board.
The TechArena Take
Marvell’s acquisition signals a strategic shift toward vertically integrated AI connectivity. The company already has substantial experience in electrical processing and semiconductor technologies underlying high-speed optical links. Lumentum adds the lasers, photonics expertise, and specialized fabrication capabilities required to produce the optical side of those connections.
The strategic value becomes clear as AI infrastructure designers evaluate optical alternatives for increasingly demanding scale-up and scale-in networks. Closer coordination between DSP development, laser technology, packaging, and manufacturing could improve performance, power efficiency, and time to market. If successful, the combined organization could become a major supplier of integrated connectivity technologies spanning advanced chip packages, accelerator clusters, and data center interconnects.
EpicSemi on Why Agentic AI Needs a New Unit of Compute
I’ve known Chloe Ma, Chief Business Officer of EpicSemi, since our days working together at Intel. Back then, our conversations centered on one company’s technology. On a recent In the Arena episode, we explored a much bigger question: Does agentic AI require a different approach to compute infrastructure?
EpicSemi believes it does. The company is developing a portfolio of technologies for enterprise agentic AI and sovereign AI, spanning compute, storage, interconnects, cooling and security. According to Chloe, conventional CPU-GPU architectures may not deliver the best economics for complex agentic workflows.
From Answers to Outcomes
Chloe sees agentic AI as the point where generative AI moves beyond answering questions to completing complex enterprise tasks.
She illustrated the difference with a workplace example. A manager asks for last quarter’s European sales figures. While a conventional AI system retrieves the data and provides an answer, an agentic system receives a broader assignment: determine why European sales are declining and recommend corrective action. This requires database queries, analysis, planning and coordination across systems, memory access and security controls. An agent may execute multiple steps before producing a useful result.
“It’s not just providing an answer,” Chloe said. “You have to deliver an acceptable outcome.”
This transition has significant implications for infrastructure design. Rather than optimizing individual inference requests, operators need to consider the performance, efficiency and security of entire workflows.
Putting the Sheeter in the Kitchen
Agentic AI workloads involve multiple types of processing. CPUs manage and coordinate tasks, while AI accelerators perform the intensive calculations required for inference. In conventional systems, data must travel between the CPU’s system memory and the GPU’s high-bandwidth memory (HBM). These transfers add latency and consume energy.
Chloe explained the challenge with a croissant-making analogy.
Making laminated dough requires a specialized machine called a sheeter. Imagine preparing dough in a San Francisco kitchen but keeping the sheeter in San Jose. Every time the dough needs another pass through the machine, someone has to transport it between the two cities.
EpicSemi wants to put the sheeter directly in the kitchen.
The company is developing what Chloe described as “a small, complete and fungible unit” of compute. Its chip combines general-purpose performance cores with AI cores, both based on RISC-V. The AI cores use vector and matrix extensions to deliver approximately 150 TOPS (Tera Operations Per Second) of AI performance. This allows the chip to handle both workflow coordination and AI inference without relying on separate CPU and GPU processors.
Both types of cores share system memory and storage, while the chip also incorporates enhanced security features. By keeping compute and memory resources on the same chip, EpicSemi aims to reduce data movement, latency and energy consumption.
“We believe this could be the unit of compute for agentic AI,” Chloe said.
Chloe envisions these units supporting specialized agents for financial analysis, legal review and IT operations. Because many expert models are considerably smaller than the frontier-scale alternatives, operators could keep them resident in memory and allocate compute resources through software orchestration.
Measuring Completed Tasks, Not Just Tokens
Much of traditional AI infrastructure was designed around the requirements of large-scale model training and high-throughput inference. GPU clusters remain effective for those workloads, but Chloe argues that agentic AI requires different performance metrics.
She drew a parallel with the transition from mainframes to warehouse-scale computing, when operators adopted large clusters of commodity servers to improve cost efficiency and scalability.
For agentic AI, Chloe argues that operators should measure how many tasks they can complete securely within a given power or total cost of ownership (TCO) budget.
“It’s really about how many agentic tasks that you actually securely complete within your power budget or within your TCO budget,” Chloe said.
That shifts the focus from maximizing raw compute performance to improving the efficiency of the entire workflow, including orchestration, memory access and inference.
Sovereignty Goes Beyond Data
As enterprises and nations invest in AI, control over the underlying infrastructure is becoming increasingly important.
Chloe described three dimensions of sovereignty:
- Data sovereignty concerns control over information.
- Infrastructure sovereignty encompasses silicon, software, security and supply chains
- Operational sovereignty requires the expertise to deploy, manage and maintain these systems independently.
EpicSemi uses the open RISC-V instruction set architecture (ISA) to support this approach. Unlike proprietary ISAs, it allows organizations to develop compatible processors without relying on a single architecture vendor.
According to Chloe, this gives nations the freedom to choose among suppliers and potentially develop domestic silicon capabilities.
EpicSemi operates in both Santa Clara and Saudi Arabia, and sovereign AI initiatives in the latter have attracted substantial investment. Across the Gulf Cooperation Council (GCC) region, organizations are investing in infrastructure and Arabic language models to meet regional needs.
Chloe emphasized that sovereignty also depends on practical capabilities. Hardware alone cannot provide operational independence. Organizations also need the software, security capabilities, supply chain relationships and technical expertise to manage their infrastructure.
Software Will Determine Adoption
EpicSemi is working with early adopters, sovereign AI initiatives, and software partners to support deployment of its architecture. Agentic workflow orchestration is particularly important: the software must assign tasks to the appropriate processors, coordinate specialized agents and allocate resources efficiently.
“Without these type of software, our hardware would be useless,” Chloe said.
The company is also pursuing opportunities with enterprises and AI startups in financial services, investment and manufacturing, where organizations increasingly combine conventional applications with AI-driven workflows.
For EpicSemi, the next challenge is to demonstrate measurable performance and efficiency gains across representative agentic workloads while building the software ecosystem required for broader adoption.
The TechArena Take
My biggest takeaway from my conversation with Chloe is that agentic AI could change how we evaluate infrastructure performance.
Tokens per second and raw accelerator throughput remain important, but they don’t capture the full cost of completing a complex, multistep task. Operators also need to account for orchestration, data movement, security, latency and overall resource utilization.
What interests me about EpicSemi’s approach is the focus on these requirements at the architectural level. Its RISC-V design combines general-purpose and specialized compute with shared memory, while its sovereignty strategy gives customers additional choices over how and where they deploy AI infrastructure.
The next step is validation. I’ll be watching EpicSemi’s agentic benchmark results and the development of its software ecosystem. Both will be critical to determining whether smaller, flexible compute units can deliver better performance per watt and per dollar than conventional architectures for enterprise agentic AI.
Listen to the full In the Arena conversation with Chloe Ma to learn more about EpicSemi.
With Validation of HBC Silicon, Qualcomm Paves a Unique Memory Path
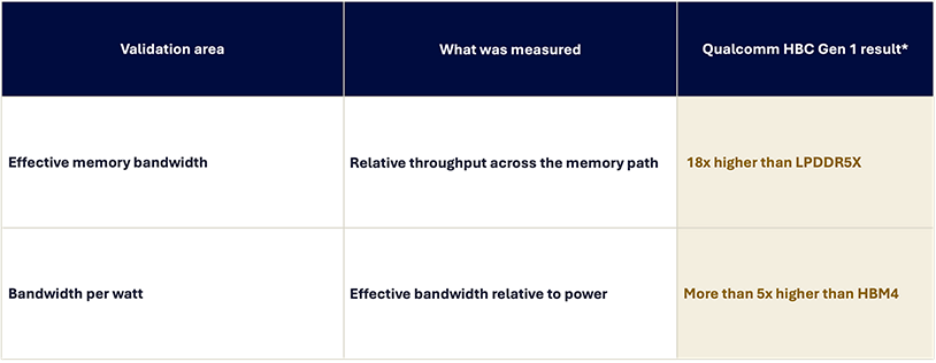
Qualcomm announced Monday that its first-generation High Bandwidth Compute (HBC) silicon has passed validation in the company’s San Diego labs, delivering 18 times the effective memory bandwidth of external Low-Power Double Data Rate 5X (LPDDR5X) and more than five times the bandwidth per watt of High Bandwidth Memory 4 (HBM4) specifications.
The result moves the stacked memory architecture toward commercialization in the Qualcomm Dragonfly AI250 inference accelerator, which is set to begin sampling in the first half of 2027. They also bring an ambition into reality. Qualcomm has argued that memory, not compute, limits AI inference in the agentic era. These results show that HBC is a viable answer to the memory wall, where moving model data between memory and compute consumes much of a system’s time and energy.
Compute Beneath the Memory Stack
As Qualcomm’s SVP & Head of DataCenter Engineering Rashid Attar explained in the announcement and in a recent webinar on TechArena, HBC stacks LPDDR Dynamic Random-Access Memory (DRAM) dies directly on top of an active AI accelerator base die, using wafer-to-wafer direct bonding and through-silicon vias. HBM, by contrast, places DRAM over a base logic die that connects back to a host processor across an ultra-wide memory bus.
Putting compute at the bottom of the stack shortens the distance data travels, which is where much of the energy goes. Because the base die handles the most bandwidth-intensive operations, its link to the main processor needs far less bandwidth.
What Qualcomm Measured
Engineers drove the silicon on industry-standard automated test equipment through production-representative data paths, using randomized weights and activations at production-representative dimensions. The tester stood in for the accelerator. It set a baseline in LPDDR5X mode, then ran an AI workload in HBC mode and compared execution time and energy.
Source: Qualcomm
Qualcomm described the results as estimates, normalizing measured silicon results to target operating conditions and comparing them with published competitor specifications. The company said redundancy and remapping are built in to work around memory defects, and that it has developed and characterized wafer-to-wafer bonding with foundry and assembly partners across multiple technology generations.
The TechArena Take
When Qualcomm introduced HBC, it made a specific argument: in the agentic era, inference performance would be won or lost in memory, and moving compute beneath the memory stack was the inside path to victory. Monday’s results put that idea into working silicon. The 18x bandwidth and 5x-plus efficiency gains now rest on a measured chip rather than an architecture slide, and AI250 sampling remains on track for the first half of 2027.
That proof lands at the right moment. Agentic workloads keep long contexts and KV caches resident, which puts memory capacity and bandwidth under constant pressure. An architecture that improves both gives operators a credible path to lower cost per token. Validated silicon shows Qualcomm’s thesis holding up and gives operators a credible path to faster, cheaper agentic inference. The next proof point is AI250 itself, and whether the gains hold at rack scale on real agentic workloads when samples arrive in 2027.
For more on Dragonfly, HBC and Qualcomm’s data center strategy, visit the Qualcomm Dragonfly Media Platform on TechArena.
Airsys: Every Watt Has a Thermal Obligation in AI Cooling
Rack densities in AI data centers are climbing faster than anyone predicted. NVIDIA’s NVL72 racks already draw well over 100 kilowatts, and the upcoming NVL576 is expected to push past 600 kilowatts. Cooling is no longer an afterthought, but one of the defining constraints on AI infrastructure deployment, performance, and economics.
At AI Infra Summit, TechArena’s Allyson Klein sat down with Jeff Moore, VP of Strategic Partnerships at Airsys, to discuss these challenges. Airsys has 30 years’ experience, having started in comfort cooling before expanding into mission-critical applications. Its technology has since earned a TechArena award for innovation in AI infrastructure.
Moore’s central message: most of the industry isn’t moving to liquid cooling overnight, and solutions must accommodate existing infrastructure while preparing for higher-density compute.
Liquid Cooling Is a Transition, Not a Switch
Hyperscalers and large-scale AI factories face the most extreme cooling requirements, but many facilities are transitioning more gradually, with GPU platforms that can still be supported by air cooling. Operators want to maximize existing space and power capacity while introducing liquid cooling without extensive capital investment or facility redesign. Supporting that phased transition, rather than forcing a complete overhaul, is where Moore sees the strongest fit for the Airsys portfolio.
Every Watt Has a Thermal Obligation
As densities rise, operators want to direct as much of their available power as possible toward compute. “Every watt that goes to the GPU has a thermal obligation with it,” Jeff explained. Cooling infrastructure must therefore accommodate both current thermal loads and the requirements of future silicon generations.
Compressed timelines add further pressure. Every delay between hardware installation and operational readiness represents lost revenue potential, so cooling has to be delivered and installed on schedule. Airsys supports production from its new half-million-square-foot global headquarters campus in Woodruff, South Carolina, as well as manufacturing facilities in Hungary and China.
Jeff also pointed to growing silicon diversity as inference spreads beyond a single vendor. GPU power requirements are increasing, while emerging 800-volt DC architectures are changing how power is distributed within AI infrastructure. Airsys emphasizes design flexibility and rapid prototyping to accommodate evolving customer specifications, component configurations, and thermal requirements.
3D Printing Changes the Cold Plate Equation
One of Airsys’s key technical differentiators is additive manufacturing. Jeff recalled standing in a booth at OCP two years ago with Airsys founder Yunshui Chen, discussing 3D-printed cold plates when industry adoption was still limited. Today, multiple companies have introduced alternative manufacturing techniques, from ECAM to stack forging.
Airsys uses laser powder bed fusion, an additive manufacturing process established in aerospace that builds metal components layer by layer from digital designs. The company works primarily with aluminum and copper but can incorporate other materials to meet specific performance requirements. Printing enables more complex internal structures, increasing the surface area available for heat transfer and improving thermal performance.
The approach also shortens design and prototyping cycles. As NVIDIA accelerates its GPU development roadmap, cooling suppliers must adapt to new thermal and mechanical requirements on increasingly compressed timelines. Where conventional cold plate manufacturing may require new tooling, additive manufacturing enables Airsys to iterate designs without the same production constraints.
Moving Beyond PUE to Power Compute Effectiveness
Power usage effectiveness (PUE) has long been the industry’s standard metric for data center energy efficiency. But PUE measures total facility energy consumption relative to IT equipment energy use, rather than how productively that energy is converted into compute. Allyson, who worked on PUE during her time at Intel, observed that the industry may have placed too much emphasis on infrastructure efficiency without adequately accounting for computational output.
Airsys has introduced a complementary metric: power compute effectiveness (PCE). Where PUE measures operating energy efficiency, PCE measures allocation or the share of a facility's provisioned power that's available for compute. The more power that can go to compute, the more AI capacity a site can support within the same grid connection.
Brownfield Facilities Aren't Left Behind
AI infrastructure conversations often focus on greenfield builds, but many operators must accommodate higher-density workloads within existing data centers equipped with legacy systems like computer room air conditioning (CRAC) units. Jeff, who recently joined a panel with Equinix and colocation providers, emphasized that these purpose-built facilities need a practical upgrade path as customer requirements evolve.
The answer from Airsys is LiquidPack, a single-phase solution designed to fit within a standard rack footprint. It uses contained impingement spray cooling, with servers installed in cassettes and substantially less fluid than conventional immersion cooling. Because it connects to existing facility water infrastructure, operators can introduce liquid cooling without a facility overhaul.
Jeff said operator response has been very positive. Applications extend to the edge, where Airsys already cools converted cell sites and telecom properties, as well as modular data center deployments.
Think in Cooling Loops, Not Cold Plates
When Airsys first began developing 3D-printed cold plates, the goal was removing two kilowatts of heat. Today, servers integrate multiple GPUs and CPUs within increasingly dense rack-scale architectures, and focusing on the cold plate alone won't cut it.
Jeff argued for evaluating the complete thermal management system, including piping, coolant properties, phase-change behavior in two-phase architectures, manifolds, and the coolant distribution unit (CDU). System-level instrumentation provides the visibility needed to monitor fluid behavior, manage operating conditions, and optimize heat removal across the entire cooling loop.
Two-Phase Cooling, Done Responsibly
Two-phase cooling offers the potential for greater heat transfer efficiency, but refrigerant selection introduces environmental, safety, and operational considerations. Jeff sees progress in the development of PFAS-free alternatives. “I think we’re going to innovate our way forward,” he said, pointing to new refrigerants that have emerged over the past six to 12 months.
Single-phase cooling remains well established, with additive manufacturing extending its capabilities through more effective cold plate designs. However, increasing thermal loads will eventually push the practical limits of coolant flow rates, operating temperatures, and heat removal capacity. Two-phase systems offer another path forward, provided the industry can establish reliable, safe, and scalable approaches to deployment.
The TechArena Take
AI infrastructure is advancing faster than traditional cooling architectures can comfortably accommodate. Yet the transition to liquid cooling won't happen overnight, and operators need solutions that address immediate thermal demands while leaving room for future generations of compute.
Airsys is approaching that challenge from multiple directions, combining additive manufacturing, system-level thermal management, and a portfolio spanning air, single-phase liquid, and emerging two-phase technologies. Its emphasis on power compute effectiveness also reflects a broader shift in how the industry evaluates infrastructure: by how much provisioned power a facility makes available for compute.
Ultimately, the next generation of AI cooling will require greater flexibility across technologies, facility types, and deployment models. Every additional watt directed toward compute creates a corresponding thermal obligation and meeting that demand will be essential to scaling AI infrastructure efficiently.
To hear more about Airsys and their innovative approach to AI cooling, listen to the full episode.

Verify, Don’t Trust: What Sovereign AI Buyers Require Now
Governments and regulated enterprises have moved sovereign AI from policy to procurement. The builders serving them say those buyers now require proof of control: where the infrastructure sits, who runs it, who can reach the data and how the buyer plans for what it cannot control.
Executive Summary
Sovereign AI has moved from policy to procurement, and the governments and regulated enterprises buying it answer to legislatures, regulators and national security processes. That accountability shapes what they require from the companies that build and run their AI infrastructure. This paper sets out four of those requirements, drawing on authoritative voices building sovereign AI infrastructure in Europe and beyond. Those requirements start with a working definition of control. From there, buyers require infrastructure whose location they can verify against a standard, along with operators and access controls they can audit, down to who holds the encryption keys. They also require a plan for the inputs no single buyer fully controls, from the supply of cutting-edge accelerators to access to frontier models. The paper closes with what a sovereign buyer should ask to see before signing.
Proof, Not Promises
Mistral closed a €3 billion Series D on Sept. 8, 2026, the largest equity round ever completed by a European technology company. The company plans to scale European compute capacity to 1GW by 2030 and to offer regional data processing to governments and companies that want AI independence from US providers. In late July, the EU opened its call for up to seven AI gigafactories, with €10 billion in public funds and at least €20 billion in expected private investment behind it.
Capacity is only half of what sovereign AI buyers need. The builders serving them say those buyers also have to prove they control it.
“‘Trust us’ isn’t an acceptable answer to a government customer. ‘Here’s how you verify it yourself’ is,” said Nidhi Chappell, Nscale’s president of AI infrastructure. “That shift — from performance-first to verifiable-first — is the biggest change in how I design.”
The shift follows from who the customer answers to. Large hyperscalers design to optimize throughput, cost per token and uptime for a single company’s roadmap, Chappell said.
“Government and regulated entities aren’t just optimizing for performance — they’re accountable to a legislature, a regulator, or a national security process,” she said. “That changes the requirements: auditability, chain of custody for hardware and data, procurement cycles that need more time, and a need to prove things rather than simply deliver them.”
Who Is Buying, and Why Now
Sovereign buyers have moved from talk to action. Eighteen months ago, their posture was rhetorical, said Jonathan Symonds, chief marketing officer at Radiant, the vertically integrated AI infrastructure company Brookfield launched in February. Now, governments are executing.
“Sovereign nations are also much more serious than they were,” Symonds said. “They are openly putting RFPs into the market.”
The trend is strongest in Europe and extends to South Korea, the United Arab Emirates and Saudi Arabia. Those buyers want speed, a fast path to first production capacity and a clear roadmap to self-sufficiency, he said.
Export controls on AI models also put model providers, not just governments, in the market for compute.
“The first beneficiary of the export controls were other model providers with fewer political entanglements,” Symonds said. “Cohere and Mistral are excellent examples.”
Those model providers now shop for compute in ways they did not six to nine months ago.
Scaleway sells control without the sovereign label. Albane Bruyas, chief commercial officer and chief operating officer at the French cloud provider, avoids the word because its definitions vary so widely.
“What we sell more and what is very interesting for our clients is that we sell a full autonomy,” she said during a recent TechArena podcast. “This means that we have control on all the value chain. This is what makes the pure difference for our clients.”

Gartner forecasts $80 billion in sovereign cloud infrastructure-as-a-service spending this year, a 35.6% increase over 2025, with governments as the main buyers. Gartner also expects more than 75% of European and Middle Eastern enterprises to geopatriate their workloads by 2030, moving them out of global public clouds and into local options, up from less than 5% in 2025. Nscale closed a $2 billion Series C at a $14.6 billion valuation in March.
The US CLOUD Act lets American authorities compel US-headquartered providers to hand over data they hold abroad. Under that law, a provider’s headquarters, not only the location of its data center, determines which government can demand a buyer’s data. In Europe, the EU AI Act requires organizations that deploy high-risk AI systems to keep the logs those systems generate for at least six months, to the extent the logs are under their control. Those obligations take effect Dec. 2, 2027.
Control They Can Define
A buyer has to define control before it can verify it. Chappell defines it this way.
“For us, sovereignty means enabling governments and enterprises to run critical AI workloads under their own legal, operational and security frameworks — with clear control over where infrastructure sits, who operates it, who can access it, and which laws apply,” she said. “That’s not only about where data resides; it’s about control of the compute infrastructure underneath it.”
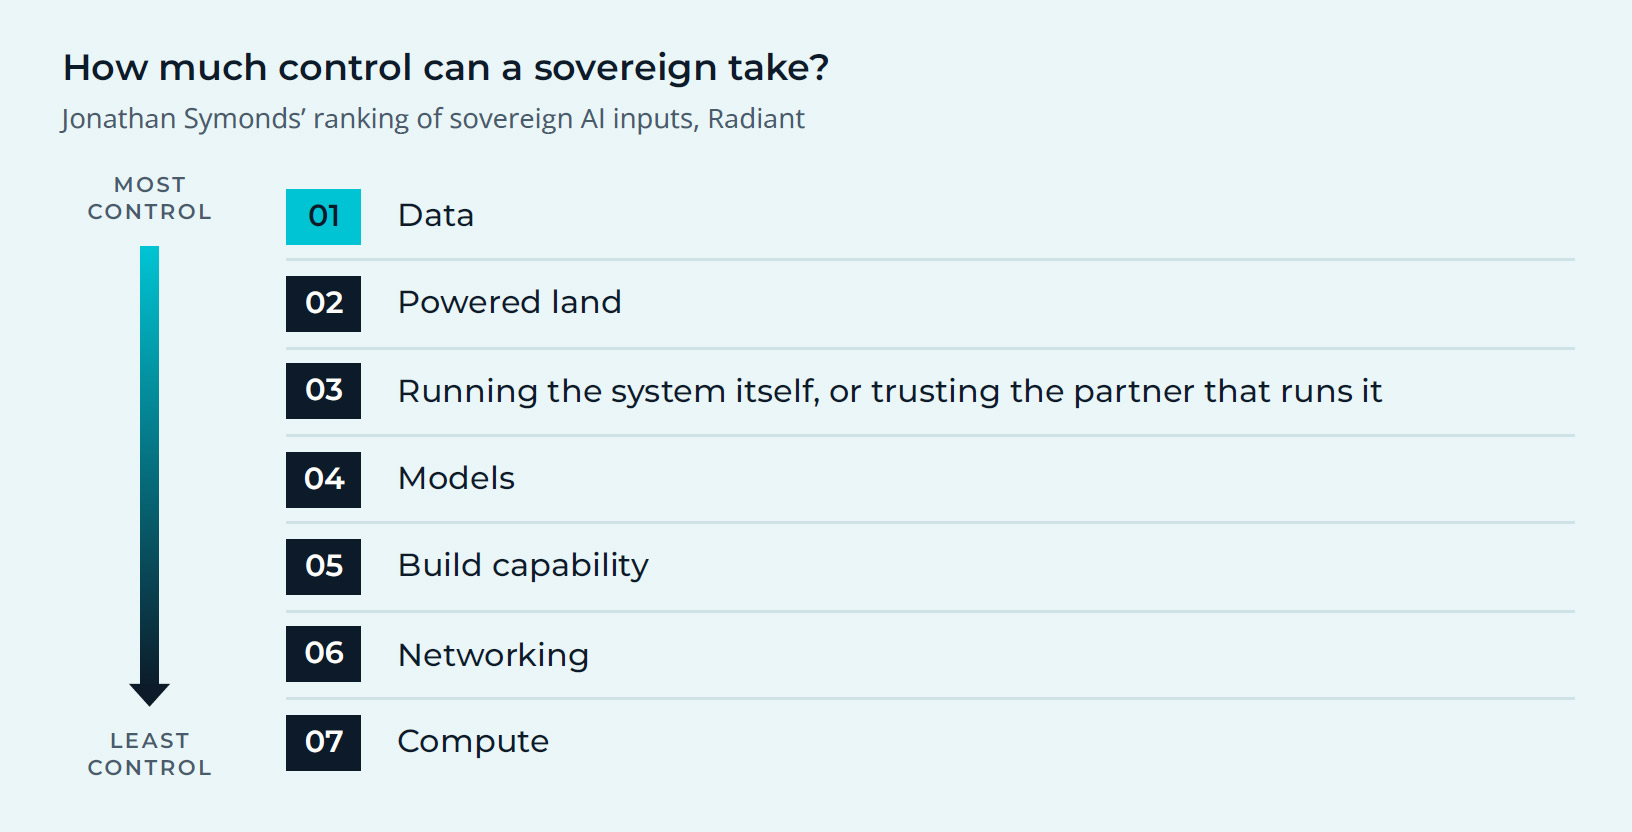
A sovereign can take more control over some inputs than others. Symonds ranks the inputs a sovereign needs, from data and land to models and compute, by how much control a sovereign can take over each. Data comes first.
“Data is the fuel,” he said. “You wouldn’t bother with sovereignty if you weren’t starting from the data layer.”
After data, Symonds ranks the remaining inputs in this order:
- Powered land
- Running the system itself, or trusting the partner that runs it
- Models
- Build capability
- Networking
- Compute
“You can own and operate the GPUs, but you cannot meaningfully control the upstream supply of cutting-edge accelerators,” Symonds said. “One does not homegrow cutting edge GPU capacity overnight.”
“Control what you can, invest there, reduce risk everywhere else,” he said.
That rule orders a sovereign buyer’s requirements. Buyers verify the inputs they control: where the infrastructure sits, who operates it and who can reach the data. They plan for the inputs they cannot fully control: accelerator supply, access to frontier models and the suppliers they depend upon.
A Location They Can Verify
Location is the first requirement a sovereign buyer verifies. In a standard public cloud region, Chappell said, “‘region’ is often a configuration setting.” Workloads and data can be routed, replicated or failed over across borders by default, and “a customer largely has to take the provider’s word for where things actually run.”
Nscale’s partnership with BT takes a different approach.
“With BT, the sites, the network paths, and the operational access are fixed to UK jurisdiction and governed by BT’s existing security and compliance frameworks, not a config toggle that could quietly change,” Chappell said.
In practice, the physical location of the hardware is known, fixed and auditable. Data does not leave the jurisdiction as part of normal operation.
“The whole environment can be independently verified against a standard, rather than just asserted,” she said.
Nscale matches location to the workload.
“Not every country needs its own hyperscale campus, so the model we’re pursuing is federated,” Chappell said.
Large training campuses sit where power is abundant and low-cost, in the Nordics and Iberia. Those campuses feed smaller in-region or in-country clusters for workloads that have to stay local. BT supplies the in-country half in the UK, with national telco infrastructure and sovereign compute layered on top, serving public sector and enterprise customers.
Location also depends on land and power, the physical inputs Symonds ranks highest.
“You can and should control your physical inputs,” he said.
In a true sovereign sale, he said, the sovereign likely owns the land and the power. Radiant designs, builds and turns up the AI factory, finances it if needed and operates it up to a point.
Power is the requirement buyers most underestimate, Chappell said.
“Most sovereign programs plan the compute procurement first and the power second, and power is what actually gates the timeline,” she said.
Nscale owns its power envelope, which changes how it designs.
“When you own the power envelope, you’re not just backing into a wattage number after the fact,” Chappell said.
Nscale designs density and storage placement around the actual power profile of each site from the start, and it throttles GPU draw dynamically rather than overprovisioning.
Operators and Access They Can Audit
The next set of requirements covers people. Symonds ranks self-operation second, right after powered land. A sovereign has to build the capacity to run its own system, even in phases, he said, or place true trust in an operating partner.
At BT, only vetted personnel operating under UK law can reach the control plane, Chappell said.
“Baseline, not premium,” Chappell said. “In a sovereign or regulated context, those aren’t things a customer upgrades into later — they’re the entry requirement to even be considered for the bid. We don’t access or inspect customer GPU workloads, and that isolation, alongside encryption, verifiable erase and firmware integrity, is built into every deployment, not sold as an add-on tier.”
Access requirements extend to the data itself. In an air-gapped, on-premises build, weights and data persist at rest in the storage system. Symonds said the deciding question there is “who has technical authority over the storage system: who controls access, encryption keys, updates, telemetry and administrative privileges.”
Most modern storage runs as software on standard server and flash hardware, Symonds said. He advises buyers to choose that software from a vendor they trust and architect it so the sovereign operator, not the vendor, retains control of keys, access, software updates and external connectivity.
Vendor domicile still counts. Some countries will not buy storage from companies domiciled in certain other countries, Symonds said, and “that is a legitimate procurement and supply-chain consideration.” Domicile does not replace technical control.
“Vendor domicile and government exposure remain relevant risk factors, but they are not substitutes for those technical controls,” he said.
Auditing access gets harder outside the data center. Chappell calls extending real-time response to the edge, at the same security bar as the core, the hardest thing a sovereign builder has to deliver. A core facility takes some of its trust from physical design: badges, perimeters, cameras. An edge node lacks those by definition, “so you have to rebuild that trust in hardware and software instead of walls, at the same latency budget.”
“The underlying principle is that physical security can’t be your only control once the node leaves the building,” she said.
Proof does not replace trust in the provider. Symonds said Radiant’s customers know the company can deliver because it holds capital, powered land, compute access and software in house.
“They have confidence we are going to be around in 18, 36, 48 months,” he said. “In that sense, trust is another differentiator.”
A Plan for What They Can’t Control
A buyer that verifies every input it controls still depends on inputs it cannot fully control. Symonds expects compute to be the hardest constraint three years out. Hyperscalers, frontier labs and major AI enterprises will continue to absorb a disproportionate share of leading-edge capacity, he said. Most governments will build 50MW to 500MW in that window, and multi-gigawatt scale will elude almost all of them.
Those governments can build data centers and procure models, Symonds said. GPUs and the networking to keep them fed will be harder to secure unless buyers place orders well ahead of time. Public-sector procurement tends to value optionality and staged commitment.
“Getting things built favors the bold,” he said.
Scarce compute raises the value of every GPU a buyer secures.
“Storage decides whether the expensive compute you’ve built actually gets used — that’s a direct line to unit economics,” Chappell said.
AI agents, software that plans and carries out multistep tasks with limited human direction, sharpen the problem. Agentic inference brings unpredictable access patterns as many agents hit shared context or memory stores at the same moment.
“Storage breaks first,” Chappell said.
Under that load, peak demand matters more than the average.
“Architectures tuned purely to averages will look efficient on paper and fail live,” she said.
Models are the second input a buyer cannot fully control. Discussing the US-China contest over model weights, Symonds reduced control to one test.
“This is all about control and, in this context, control is the ability to rescind access,” he said.
Washington and Beijing increasingly regard the weights themselves as strategic technology, Symonds said. In his reading, China wants the ability to pull its free but very good models if the US pulls its expensive but cutting-edge ones. Open weights work the other way.
“Once the weights have been openly released, they are extraordinarily difficult to claw back,” he said. “Open source models offer an opportunity for sovereigns to have real control and real personalization.”
His advice to buyers: “de-risk your model supply chain now.”
Suppliers are the third. Digital buyers too often forget a rule the industry treats as basic, said Albane Bruyas of Scaleway. A company that depends on one strategic supplier has no fallback if that supplier fails, raises prices or receives a data request from a foreign government. In industry, she said, a buyer of a strategic component chooses at least two suppliers, so a fire at one factory still leaves somewhere to buy.
Open hardware makes the second supplier possible, she added. The more open the hardware, the more suppliers an operator can buy from, and more suppliers mean better prices and more capacity. Scaleway buys European when it can, because in her view purchase orders, not grants, build an ecosystem.
Owning the full stack reduces dependency from the other direction. Nscale owns its power, data centers, compute and software, which removes subcontractors from the chain a sovereign buyer has to trace. Radiant builds on the same model.
“Our core advantage was, and continues to be vertical integration,” Symonds said. “Others can match different components, capital, powered land, compute access and expertise, software, but no one yet has demonstrated the ability to unify them all.”
The TechArena Take
Verifiability now stands alongside performance as a requirement in sovereign AI procurement. We expect the sovereign builds of the next three years, most of them in the 50MW to 500MW range Symonds describes, to go to builders who can show a buyer, line by line, which inputs the buyer controls and how a third party can check each one.
- The standard against which the site’s jurisdiction is independently verified.
- The people who can reach the control plane and the law they operate under.
- Who holds the keys, updates and telemetry for the systems where data and weights persist.
- The power plan, before the compute order.
- The plan for accelerator supply, model supply and a second supplier.
We see verification becoming part of the product itself. Builders that document jurisdiction, operator access and data control before the first workload runs give buyers what a legislature or regulator will ask to see. We expect those builders to turn sovereign RFPs into production capacity fastest. For sovereign AI buyers, proof is now part of what they pay for.
1. Rebecca Szkutak, “Mistral raises €3B as sovereign AI becomes big business,”TechCrunch, Sept. 8, 2026. [Confirm byline.] https://techcrunch.com/2026/09/08/mistral-raises-e3b-as-sovereign-ai-becomes-big-business/
2. European Commission, “EU launches AI Gigafactories call to boost Europe’scomputing capacity and unlock more than €30 billion in investment,” July 30,2026. https://digital-strategy.ec.europa.eu/en/news/eu-launches-ai-gigafactories-call-boost-europes-computing-capacity-and-unlock-more-eu30-billion
3. Deanna Oothoudt, “Brookfield Bets on Sovereign AI With Radiant and Ori Deal,”TechArena, February 2026. https://techarena.ai/content/brookfield-bets-on-sovereign-ai-with-radiant-and-ori-deal
4.Gartner, “Gartner Says Worldwide Sovereign Cloud IaaS Spending Will Total $80Billion in 2026,” Feb. 9, 2026. https://www.gartner.com/en/newsroom/press-releases/2026-02-09-gartner-says-worldwide-sovereign-cloud-iaas-spending-will-total-us-dollars-80-billion-in-2026
5. Gartner, “Gartner Identifies the Top Strategic Technology Trends for 2026,”Oct. 20, 2025. https://www.gartner.com/en/newsroom/press-releases/2025-10-20-gartner-identifies-the-top-strategic-technology-trends-for-2026
6. Nscale, “Nscale Raises $2 Billion in Series C — the Largest in EuropeanHistory,” press release, March 2026. https://www.nscale.com/press-releases/nscale-series-c
7. Jennifer Daskal, “Unpacking the CLOUD Act,” eucrim. https://eucrim.eu/articles/unpacking-cloud-act/
TechArena Launches Mentoring to Fill the Grace Hopper Gap
I founded TechArena on a simple belief: the best advancements in technology come from a wider range of voices than our industry usually puts on stage. That’s why this month’s cancelation of the Grace Hopper conference hit so hard. For more than 30 years, Grace Hopper has been where women in computing found mentors, sponsors, and their first real sense that they belonged in this industry. Grace Hopper also leaned into allyship, itself building the widest expanse possible for connection and community.
Anyone who has sat in a room or attended a conference where no one resembles you knows how important this is. Its loss is more than a canceled event. It leaves a hole in the pipeline at the exact moment the leaders of the AI era are being chosen. I’ve spent my career in this industry, from Intel and Micron, to building TechArena, and I know how much of career advancement happens through mentors, allies, champions, and people willing to tell you the unwritten rules. When the rooms where that happens disappear, talented people stall.
That’s why we’re launching TechArena Advisory mentoring now with a sprint of speed-round sessions. This program pairs emerging leaders with our advisors and leaders from our network. Operators who have run businesses, launched platforms, and made the hard calls at the highest levels of tech are dedicating their availability to engage. Our Advisors are collectively grateful and humbled by the collective outpouring of participation from executives who have shaped our industry for decades.
Anyone who is seeking help with connection or earned insight can simply visit our website and sign up for an available slot between November 2nd and 4th. Lakecia Gunter and Raejeanne Skillern, our TechArena Advisors who were planning to teach at Grace Hopper this year, alongside VSORA Chair Sandra Rivera, will also be delivering their course as planned online for all to access. The course is titled, "From Impact to Influence: How Women in Tech Can Prepare for Board Roles." And we're offering any other presenters the opportunity to host sessions on our platform as well.
This program comes from the same commitment to talent across all vectors of inclusion that shapes whose voices we publish, who we put on stage, and how we build our own team. If we want an AI era that works for everyone (and we certainly do), the people building it have to come from everywhere, and that work can’t pause because a conference did.
Graid Technology Takes Aim at the Inference Memory Wall
Storage spent most of the last two decades as the part of the server nobody had to think about very hard. It was evaluated on capacity, reliability and cost per gigabyte, and the interesting engineering happened elsewhere. That is not where the industry is today. As deployments shift from training to inference, the question of where a model keeps its working context has become a performance problem with real money attached to it. I recently sat down with Garrett McKibben, senior director of technical marketing at Graid Technology, to talk about what inference workloads are doing to the memory and storage hierarchy. Garrett and I have been talking about the blending of that hierarchy for a long time, and this conversation was the first one where the economics of it felt concrete.
The One Lane Bridge
Graid Technology has been in market for about five or six years, built around a premise that sounds almost contrarian: remove the RAID controller entirely, let host memory talk directly to the SSDs, and accelerate the I/O path with the GPU. The reason comes down to arithmetic.
“Any single PCIe by 16 Gen 4 was limited to 30 gigs of throughput. Gen 5 is limited to 60 gigs of throughput,” Garrett said. “The analogy we like to use is you've got a four lane highway and to get to your storage, you have to go down to a one lane bridge.”
Buyers have invested heavily in NVMe performance, then sipped it through what he called a tiny coffee straw. That mismatch was the company’s original opening. It has since expanded. The company acquired the VROC assets from Intel roughly a year ago, with VROC by Graid Technology arriving in the coming months. Now it is pointing its efforts toward applying the same I/O thinking from its founding to agentic AI and KV cache.
The Economics of Remembering
As attention shifts from training to inference, the gating factor is not compute. Garrett pointed instead at capacity and the cost per gigabyte across the hierarchy. HBM on a Blackwell part tops out near 180 gigabytes at $50 to $80 per gigabyte. System DRAM improves the economics at $5 to $8 per gigabyte but remains finite. NVMe runs $0.08 to $0.12 per gigabyte with effectively unbounded capacity.
The instinct when a model runs out of room for its KV cache is to add GPU memory. Garrett’s math says that path closes quickly.
“With that limited amount of HBM, in our calculations, you run out of concurrent users after about three or four users,” he said. “As much as maybe NVIDIA would love each of us to go buy a new Blackwell 200 for every three users, it’s not feasible.”
Fetch Versus Recompute
The test for any storage tier in this role is simple to state and harder to satisfy. A GPU that loses its context can always recompute it, and it does so quickly. Storage only earns its place when retrieval beats recalculation.
“Fundamentally, fetch has to be faster than recompute,” Garrett said. “If it takes longer for the GPU to go fetch it…than it takes to compute, then there’s no value.”
Graid Technology published results measuring exactly that. With no KV Cache, recomputation took 29.5 seconds; adding MD RAID raised it to 36.6 seconds. SupremeRAID reduced the KV-cache retrieval path to 9 seconds—3.2x faster than recomputing the context. Garrett was careful not to oversell the finding, noting it holds in that particular scenario rather than every case, but the direction is the point: with an unconstrained link to NVMe and long context windows, fetching wins.
The GPU-side approach costs less than most people assume. The software-only version runs on the GPUs already in the box, consuming roughly 4 percent of capacity, about six streaming multiprocessors, and releasing them the moment the I/O completes. That leaves the CPU free for the applications it is increasingly responsible for orchestrating.
What Rack Scale Changes
The shift from components to rack-level systems makes the storage question harder rather than easier. A request may be initiated on one GPU and serviced elsewhere, which means the context has to be findable across the rack or the pod without adding back the latency the design was meant to remove. Graid Technology is working with open source frameworks including LMCache and Mooncake toward a single namespace that can meet those latency requirements.
Garrett framed why any of this matters with a simple metaphor. He compared a GPU without its KV cache to walking into a room and forgetting why you went in, then having to retrace your steps. With agentic workloads running for hours or days, that retracing is not a minor inefficiency.
“There’s a difference between having them fully utilized recalculating the same thing time and time again versus retrieving it and then moving to the next step,” he said. “It’s no longer about FLOPS. It's about enabling your engineers or your users to get results through their agents.”
The TechArena Take
The blending of the memory and storage hierarchy has been a talking point for the better part of a decade. KV cache overflow now gives it a number attached to it. Fetch versus recompute is a clean test, and it changes the buying conversation: a team with a system that retrieves context instead of recomputing it is not saving on storage, it is recovering GPU cycles it already paid for. That is a materially different business case, and it lands with a different set of decision makers.
The open question is rack scale. Single-server results are encouraging, but inference is becoming a distributed problem, and locating a given KV cache across a pod without reintroducing latency remains unsolved. We’ll be watching which approaches holds up as the unit of deployment keeps getting bigger.
AI Inference is Changing the Entire Data Center
The first generation of AI infrastructure was built primarily for training: moving enormous datasets fast enough to keep GPUs productive through large, compute-intensive runs. Production inference introduces a different set of demands. Time to first token, token throughput, latency, tokens per watt, and customer experience all influence how operators measure success. Agentic AI adds another layer of complexity, with longer, multistep workflows that generate and reuse growing amounts of context.
At Yotta 2026, TechArena CEO and founder Allyson Klein moderated two panels exploring these implications across AI infrastructure. The first, “The Inference Storage Problem: Rethinking Data Architecture for AI at Scale,” examined the demands inference and agentic workloads place on compute, networking, memory, and storage. It brought together Marc Austin, CEO and co-founder of Hedgehog; Sam Clarke, vice president of neocloud and AI business development at VDURA; Angel Camacho, director of product marketing at Western Digital; and Betsy Chernoff, principal AI product marketing manager at WEKA.
The second panel, “Tokens per Watt: Efficiency as the Fastest Path to AI Capacity,” extended the conversation to power, cooling, and facility infrastructure. Chernoff returned, joined by Peter Panfil of Vertiv and Sean Corcoran, Vice President of Sales for PowerOne at Airsys. They explored how increasingly dynamic AI workloads affect power demand, thermal management, and the physical limits of data center capacity.
Together, the discussions revealed a common challenge: delivering more useful AI output requires coordinating resources across the entire infrastructure stack. As inference becomes a larger share of AI workloads, operators must consider how compute, memory, storage, networking, power, and cooling work together to determine performance, efficiency, and capacity. From the conversations, several key insights emerged.
Inference Changes What Infrastructure Needs to Optimize For
Operators increasingly need infrastructure that serves training and inference simultaneously. While training prioritizes completing large compute jobs and keeping GPUs supplied with data, inference introduces new performance requirements. Distributed inference also places greater demands on networking and data movement as pilots scale into production. Angel noted that pilots can comfortably hold large amounts of data in RAM, but that approach becomes prohibitively expensive as applications expand to hundreds or thousands of users.
GPU utilization can also be misleading. An accelerator may remain highly utilized while repeating computations unnecessarily, so operators need to evaluate useful output, response times, and the energy required to generate each token.
“Our job is really to make sure that the GPUs...keep working, keep the beast fed, and also on the inference side, make sure they’re not doing the work twice,” Sam said.
These changing workloads also affect facility infrastructure. Peter described GPU demand shifting rapidly between relatively low and high loads. Electrical systems experience those fluctuations immediately, while thermal systems respond to the resulting heat with a delay. Power and cooling must therefore adapt to increasingly dynamic compute requirements.
“This is not our father’s cloud world anymore,” Peter said. “This is a dynamic world in which the systems are interdependent.”
Inference efficiency, in other words, runs from the application through compute, memory, storage, and networking, all the way to power delivery and heat rejection.
Keeping GPUs Productive Requires Managing Data and Context Intelligently
Agentic AI makes context management an increasingly important infrastructure challenge: agents perform multistep tasks that depend on information generated earlier in the workflow, requiring systems to retain and retrieve growing amounts of context. The key-value (KV) cache preserves this information so models can reuse previous computations.
“Context matters. It’s important that our agents remember what we’ve been doing,” Angel said. “Otherwise, we will have to recompute all that we’ve been doing, spending GPU time.”
High-bandwidth memory (HBM) provides fast access to data but remains expensive and capacity-constrained. Betsy described how storage can extend the memory hierarchy by holding KV-cache data that doesn’t need to remain in HBM, then returning it when required. “We were able to take from high bandwidth memory all of this cache and hold it on storage and then send it back to the GPUs as quick as DRAM or as quick as the system needs,” she said.
This approach allows frequently accessed context to remain close to the GPU while less urgent information moves to lower-cost storage tiers. It also helps reduce unnecessary recomputation, freeing accelerator capacity for new work.
Betsy emphasized that different stages of inference place different demands on compute and memory. Prefill is compute-intensive, while decoding depends more heavily on memory bandwidth. As context windows expand and agentic workflows become more complex, managing data placement across memory and storage becomes increasingly important.
The implications extend to existing GPU fleets. Software-defined infrastructure, GPU mobility, fewer unnecessary data copies, and efficient offloading can help operators extract more useful work from deployed accelerators.
Every unnecessary GPU cycle consumes power and limits available compute capacity, making effective context management critical to inference performance and infrastructure economics.
The Bottleneck Is Moving Beyond the GPU
As inference workloads become more complex, networking plays a greater role in bridging compute with the memory and storage resources it needs. Marc described the network as a bus connecting different levels of the memory hierarchy, from on-chip SRAM to flash storage.
That relationship has implications for network topology too. Training and inference may require different architectures, particularly as storage becomes more directly involved in moving KV-cache data. Disaggregated inference adds another consideration, allowing different stages of a workload to run on resources suited to their computational requirements, while latency-sensitive applications may also drive infrastructure closer to end users.
The constraints also extend beyond data movement. Higher rack densities have increased the importance of thermal management, with direct-to-chip liquid cooling becoming central to supporting more powerful accelerators. Air cooling still has a role, making hybrid approaches important as facilities accommodate a wider range of equipment.
These decisions require closer coordination between mechanical, electrical, and compute teams, since cooling architecture affects facility power consumption and how much capacity remains available for IT equipment.
“It has to be the whole architecture of the data center,” Sean said, describing a design approach that extends “from the chiller to the chip.”
As accelerators become more powerful, infrastructure design increasingly determines how effectively their capabilities can be used.
Optimize the System, Not Just Its Components
Enhancing the performance of an individual component doesn’t necessarily improve the efficiency of the entire AI infrastructure system. Decisions about compute, memory, networking, storage, power, and cooling need to account for how those resources interact before deployment.
“The biggest piece is to think strategically around how you architect across your infrastructure,” Betsy said. “Certainly starting from the GPU, but in addition to that, you have to consider networking [and] storage...well before you start to build.”
The same principle applies to facility infrastructure. “It’s a system. It’s got to be treated like a system,” Peter said. Optimizing individual subsystems can improve their performance without delivering corresponding gains across the facility.
The growing importance of storage illustrates how quickly infrastructure priorities can shift. Betsy noted that roughly a year and a half earlier, storage received little attention in AI infrastructure discussions because it represented a relatively small share of the bill of materials. Today, its role in supporting inference makes it a much more consequential architectural consideration. The challenge is to evaluate design decisions by their effects on overall performance, capacity, and efficiency, rather than the capabilities of any single component.
New Workloads Require New Measures of Efficiency
As inference becomes a larger share of AI workloads, operators need metrics that connect infrastructure performance to useful output.
Angel emphasized the importance of defining success before deciding what to measure. “First of all, metrics. You cannot find success if you don’t measure it,” he said. “You need to first establish what you really want to do. What is the outcome that you are looking for?”
That principle extends to facility infrastructure, where conventional efficiency metrics don’t always capture how much useful AI work a data center produces. Peter advocated measuring tokens per second per watt to connect computational throughput with energy efficiency.
Sean introduced power compute effectiveness (PCE), a metric examining how effectively provisioned building power supports provisioned IT load. At data center scale, even modest improvements in electrical and thermal efficiency can translate into meaningful capacity and cost benefits.
The shift is reaching individual infrastructure components, too. Betsy noted that WEKA’s benchmarks now include tokens per watt per second, reflecting growing interest in evaluating storage through its contribution to overall AI efficiency.
Together, these measures help operators connect workload performance, infrastructure utilization, and facility economics.
The TechArena Take: Start With the Outcome, Then Architect Backward
The central lesson from both panels is that AI infrastructure design must begin with the workload and the outcomes operators need to achieve. Establish the metrics that define success, then architect backward across compute, memory, networking, storage, power, and cooling.
Peter explained the risk of approaching those decisions independently: “If we treat it as the individual subcomponents, we might be able to optimize the performance on one of those subcomponents, but we’re not going to optimize the performance out of the system.”
As inference and agentic AI reshape infrastructure requirements, the ability to coordinate resources across the entire data center will increasingly determine how much useful work operators can deliver from their available capacity. In the inference era, the data center is no longer just the place where AI runs, but part of the AI system itself.
The Memory Problem Is Geometry: Ventiva on Cooling for Local AI
As AI hardware evolves, bringing memory closer to compute has become a critical design priority. Carl Schlachte, chairman, president and CEO of Ventiva, calls it the investment thesis of the decade. But it requires rethinking the physical space occupied by conventional cooling systems.
Carl returned to In the Arena with TechArena’s Allyson Klein at the 2026 AI Infra Summit, following a conversation last year, when he previewed a significant demonstration planned for CES 2026.
Ventiva develops thermal management technology for applications ranging from consumer electronics to data centers. Its solid-state airflow technology offers a highly modular cooling solution, creating new opportunities for component placement and system design.
Rethinking Laptop Cooling
Conventional laptop motherboards typically accommodate two fans measuring approximately 55 millimeters in diameter, with semicircular cutouts on either side of the board. This configuration consumes valuable space that could otherwise support memory, connectivity, and other components.
At CES 2026, Ventiva demonstrated an alternative architecture featuring a rectangular motherboard with cooling concentrated toward the back. The design delivered comparable thermal performance to a conventional fan-cooled laptop while operating silently, with no moving parts.
The improvement extended beyond acoustics and thermal performance: eliminating the fan cutouts also freed motherboard space for additional components. For Ventiva, this represented a shift from solving a thermal management challenge to enabling new possibilities in system architecture.
Generating Airflow Without Moving Parts
Ventiva uses electrohydrodynamic (EHD) flow to generate airflow without mechanical fans. Its compact rectangular ionic cooling modules recover the physical board space used by conventional fans. This gives designers the ability to add more memory, storage, battery capacity, or other new components. For local AI, that flexibility helps address a critical design constraint: finding room for more memory closer to the processor.
Why Local AI Depends on Memory Proximity
The growing importance of inference and agentic AI is changing how system architects think about memory capacity, bandwidth, and physical placement. Carl argued that many major advances in AI infrastructure, including optical interconnects and new communication architectures, address the same underlying challenge: reducing the distance and communication overhead between memory and compute.
For local inference, that constraint becomes especially significant. According to Carl, memory supporting effective on-device AI needs to sit approximately 15 to 25 millimeters from the processor complex. Conventional laptop fans compete for that space, particularly as CPU and GPU packages become larger and more power-intensive.
But processor specifications alone don't tell the full story. A laptop may offer substantial AI compute capability, measured in trillions of operations per second (TOPS), while its practical inference performance also depends on memory capacity, bandwidth, and how efficiently it can access model data.
Ventiva’s ultra-thin modular cooling solution creates room to position additional memory closer to the processor, potentially supporting larger models without increasing the device's external dimensions.
Carl sees this as an opportunity to run more AI workloads locally rather than relying exclusively on centralized infrastructure: “You can build a data center $3,000 at a time if you did it the right way.”
The idea is to equip individual machines with sufficient compute and memory to run appropriately sized language models. Rather than sending every inference request to the cloud, users could execute suitable workloads directly on their devices, reserving remote resources for more demanding tasks.
Ventiva doesn't replace established thermal technologies such as vapor chambers or heat pipes. Its solid-state airflow works alongside them, potentially improving heat removal while freeing space for other components.
The economics could be equally significant. Local inference can reduce recurring cloud computing costs by using hardware already deployed to end users. As more workloads become practical on client devices, organizations may be able to handle routine AI tasks without paying for remote compute on every request.
From Thermal Component to Platform Architecture
Carl described a broader change in how Ventiva engages with laptop manufacturers. Rather than discussing cooling as an isolated subsystem, the company is increasingly involved in conversations about motherboard layout and overall platform design.
A rectangular motherboard can simplify manufacturing by eliminating large cutouts associated with conventional fan assemblies. It may also allow more direct routing between I/O components and the processor, reducing the need for signal repeaters and potentially lowering system costs.
By changing where cooling hardware sits, manufacturers gain greater flexibility in how they allocate space, route connections, and integrate memory.
Carl also expects local AI capabilities to influence laptop purchasing and replacement cycles. As devices handle more inference workloads, buyers may place greater value on performance and longevity. This could challenge traditional three-year refresh cycles and the role of laptops as terminals for cloud-based applications.
The external form factor may remain familiar. Carl expects the clamshell design to persist, with more substantial changes occurring inside the chassis.
Addressing the Thermal Orphans in AI Servers
Ventiva’s solid-state cooling technology also has applications in data centers. As AI server power densities increase, CPUs, GPUs, and high-bandwidth memory increasingly rely on cold plates and direct-to-chip liquid cooling. This transition reduces the need for conventional fans around high-power processors, but creates challenges for components that still depend on airflow.
In traditional server architectures, air moves from the front of the chassis toward the rear, absorbing heat as it passes through the system. Reducing fan capacity can leave downstream components with both less airflow and higher inlet temperatures. Carl calls these components thermal orphans: boot-optimized storage, SSDs, and other devices toward the rear of the server that may not justify dedicated liquid cooling but still require effective thermal management.
Failures in these components can affect the availability of the entire system. Carl noted that even a 5% failure rate in rear-mounted storage can undermine overall server availability, regardless of the performance of the GPUs at the front.
Ventiva’s approach delivers localized airflow directly to these underserved devices without requiring major changes to existing hardware designs. Form factor is particularly important, as manufacturers of rear-mounted cards are reluctant to redesign established mechanical configurations. A cooling solution that fits within existing dimensions and delivers a 5% to 10% improvement could offer a compelling advantage.
In the server, the goal is to supplement liquid cooling, not replace it. Targeted solid-state ionic cooling modules can operate alongside cold plates, addressing thermal requirements that direct-to-chip systems do not cover.
Carl described initial skepticism from thermal engineers accustomed to designing around mechanical fans, but once they saw airflow delivered into previously impractical locations, the discussion shifted toward additional applications.
Bringing Solid-State Cooling to the Data Center
Ventiva's data center business is focused on targeted improvements rather than replacing established cooling infrastructure. Carl identified rear-of-rack components as a practical entry point, since these devices can often be replaced independently of broader server or facility upgrade cycles. This creates an opportunity to improve thermal performance without waiting for the next platform generation.
A replacement card that operates more reliably or delivers better performance within the same mechanical envelope could justify a price premium, particularly when component failures threaten server availability. For Ventiva, this offers a potentially faster path to adoption than integration into new server architectures requiring multiyear design and qualification cycles.
The TechArena Take
Ventiva's technology demonstrates how thermal management decisions increasingly influence AI system architecture.
Using ultra-thin cooling modules in laptops can free motherboard space for memory closer to the processor, addressing a critical constraint on local inference. In data centers, targeted solid-state airflow can support components that remain dependent on air even as high-power processors transition to liquid cooling.
The broader opportunity is to give system designers greater freedom to allocate space according to computational requirements rather than the dimensions of conventional cooling hardware.
The implications for local AI are particularly significant. As more inference and agentic workloads become viable on client devices, AI infrastructure could become increasingly distributed across enterprise laptops and other endpoints.
Realizing that potential requires manufacturers to consider motherboard layouts, memory integration, and thermal architecture together. Ventiva's ongoing discussions with OEMs suggest that this design conversation is already underway.
Listen to the full In the Arena episode featuring Carl Schlachte.
Agentic AI Is an Open Systems Challenge...and Opportunity
OCP Global Summit week opened for me with brunch and a question that has percolated in my mind all year: What does it take to run AI agents in production? MiTAC Computing hosted its Executive Tech Forum on Monday morning , and I had the pleasure of moderating a panel with Intel, SK hynix, Solidigm and MiTAC under the title Powering the Agentic Era: Compute, Memory, Storage and Scale.
Each company took a few minutes to make the case for the layer it builds. Assembled end to end, the four presentations delivered a comprehensive view on how innovation is accelerating across the system and the data center. Only in working together can we solve this open systems challenge that is becoming more urgent. Agentic AI changes the demand on every part of a rack or pod level platform at once, and the companies that treat the challenge as a single design problem will deliver to true operator requirements. Here is more of what I took from the room.
From Training Once to Agents All the Time
SK hynix America’s Vis Valluri, senior director of industry intelligence, set the frame with a simple progression. Training happens once. Inference runs in real time. Agentic AI runs all the time. He made his claim citing data from OpenRouter and a16z showing that agents overtook humans as the main source of token traffic early this year, with token usage up 14 times since.
The mechanics of agentic workflows explain this surge precisely. A regular inference request makes one pass through prefill and decode and returns a response. Simple and linear! An agent works in a loop: prefill, decode, call a tool, observe the result, then fold that result back into the context for another round of prefill. The KV cache grows with every turn. Valluri put the consequence in one number. More than 85% of agent tokens come from cached prompts, which means agents spend most of their time rereading context they already hold.
That single behavior sets up everything the other speakers had to say and defined a challenge across compute, memory and storage working tightly in tandem.
Compute Sits at the Foundation
Gary Brown of Intel opened his segment with a message that compute acts as a foundation to memory, storage, broader infrastructure (don’t forget the network!). As the resident CPU builder, he made the case for compute with throughput data.
Brown showed Intel Xeon 6 against competing CPU instances on healthcare agent workloads covering reasoning, security and control operations, laying out performance benchmarks of the alternative platforms. And while Intel was seeking a performance leadership win, the bigger takeaway for me is that in the agentic era, core functions of workload management matter a lot... and these are the realm of CPUs.
Intel’s own recent announcements argue that as AI turns agentic, the bottleneck moves toward orchestration, concurrency and data movement. Brown’s portfolio slide spread agentic scale across what Intel calls the intelligence and execution layers, with GPUs handling prefill. An agent spends much of its life between model calls, running tools and checking results. Someone has to schedule all of that, and the processor is a natural orchestrator.
Memory Gets New Floors
Valluri took Intel’s view and built from it with a memory centric perspective on the same challenge. SK Hynix sees the hierarchy being rebuilt with new tiers that fill the gaps between SRAM, HBM, DRAM and SSD. He laid them out from fastest to largest: a G0.5 tier of 3D-stacked DRAM with near-SRAM speed, HBM at G1, a G1.5 tier of stacked flash called HBF offering roughly 1 TB at terabit-per-second scale, conventional DRAM, a G2.5 tier of CXL-pooled memory in the multi-terabyte range, and SSD beneath it all.
The demand driver he chose was personal agents, pointing to Meta’s personal agent running on Muse Spark. This agent remembers details you mentioned once, keeps working after you close the app and runs in a dedicated cloud VM for each user. Persistent context that grows per user means more memory at every tier. When I think about the scale of that arithmetic across a large user base, the new tiers look like necessities rather than options, and the importance of memory and storage innovation argue to take center stage as the existential challenge of agentic performance.
The Price of a Prompt
So where was storage in all of this? Enter Solidigm’s Ace Stryker. He made the bluntest case of the discussion, using simple math as his tool. He started with a 14-word question: what’s a cool bird I might see when I’m in San Jose next week? That prompt is 18 tokens. The model processes far more. System prompt and policies account for 10,000 tokens, retrieval for 15,000, tool schemas for 5,000 and conversation history for 12,000. The total reaches 42,018 tokens. My guess is, in reality, we could argue it being even higher.
And... that context has to live somewhere. For one user making one request, Stryker calculated about 13.1 GB of KV cache, scaled from NVIDIA’s figure of 40 GB at 128K tokens for Llama 3 70B at FP16. Multiply by concurrent users and sessions and the memory bill scales quickly.
Solidigm’s answer to drive efficiency into the equation is to transfer that model state on SSD and restore it rather than recompute it. In work with Metrum AI, retaining KV cache on a Solidigm D7-PS1010 cut time to first token from 31 seconds to 2.8 seconds in a single-user sports archive scenario. In a separate video analytics test, pairing KV cache with DiskANN retrieval lifted queries per second by 14%, from 2,071 to 2,371 at 1,024 query threads. Stryker flagged these as separate results rather than a combined speedup, and I will repeat that caution here. He closed on a line that deserves a spot on every infrastructure budget review: every token has a resource cost, and every resource has a dollar cost.
Rack-Scale Reality
MiTAC Computing ’s Raymond Huang took the conversation from cutting edge silicon innovation to system delivery at scale, under the banner, “Where AI Power Meets Rack-Level Scalability.” Silicon only matters once it ships as a working system, and his slides were about that last mile and connecting acute operator requirements in a couture fashion with bespoke systems leveraging industry standards.
MiTAC cited more than 30 MW of rack-scale manufacturing power in 2026, capacity for 5,000 racks per month, networking up to 800 Gb/s and power readiness from 480 VAC up to 800 VDC. The MiTAC California footprint anchors this: It's Newark site features an NPI direct liquid-cooling facility, while San Jose provides dedicated liquid-cooling manufacturing. A mega-scale, six-building campus in Fremont further strengthens the company’s ability to design, validate, and produce advanced computing solutions. From PCB and motherboard design to barebone, systems and complete AI clusters, MiTAC delivers vertically integrated, in-house engineering that accelerates time to market and ensures end-to-end quality. On the product side, Huang showed a 52U high-density liquid-cooled rack, including a direct liquid-cooled MI355X GPU configuration, and a 256-GPU cluster example with in-row coolant distribution and a separate aggregation switch rack.
MiTAC pairs the hardware with open firmware and management software called MiOBMC™, MiOPF™ and MiCoreView™, and with ecosystem partners including DDN, Rafay and Canonical Ubuntu. A partnership with Tonomia targets modular AI data centers. Its Diamond Cooling approach aims to keep token generation throttle-free at standard data center temperatures, which could trim power and cooling costs if it performs as described.
The delivery model closed the loop. US-based engineering and project management, local system and rack integration, and a build-to-inventory approach aim to shorten lead times for customers who cannot wait out a long supply chain.
The TechArena Take
From soup to nuts, one word runs through the discussion as a throughline. Agents carry context from step to step, and context is state. State has to live somewhere, and every element of infrastructure is now being asked to hold more of it, closer to the processor and for longer. SK Hynix described the tiers that hold it. Solidigm priced it in both gigs and dollars. Intel claimed the baton with the statement that the processor orchestrates it. MiTAC showed how to package it all into racks that arrive on schedule.
Run the memory math once and the stakes come into focus. A single request can carry 13.1 GB of cache, and a personal agent maintains its memory between sessions. The capacity question becomes a per-user number multiplied by a sea of agents and humans. Size up that investment, and the case for re-tiering and deeper performance tier SSD use comes into acute focus.
Capacity plans built around model size and GPU count will miss the largest cost driver in agentic deployments. Plan around the workflow and sustained memory: how large does it grow per session, how many sessions run at once, and where each piece of it should live. Operators who answer those questions across compute, memory, storage and rack design together leveraging all of the standards the OCP community provides will build agent infrastructure that scales at speed.
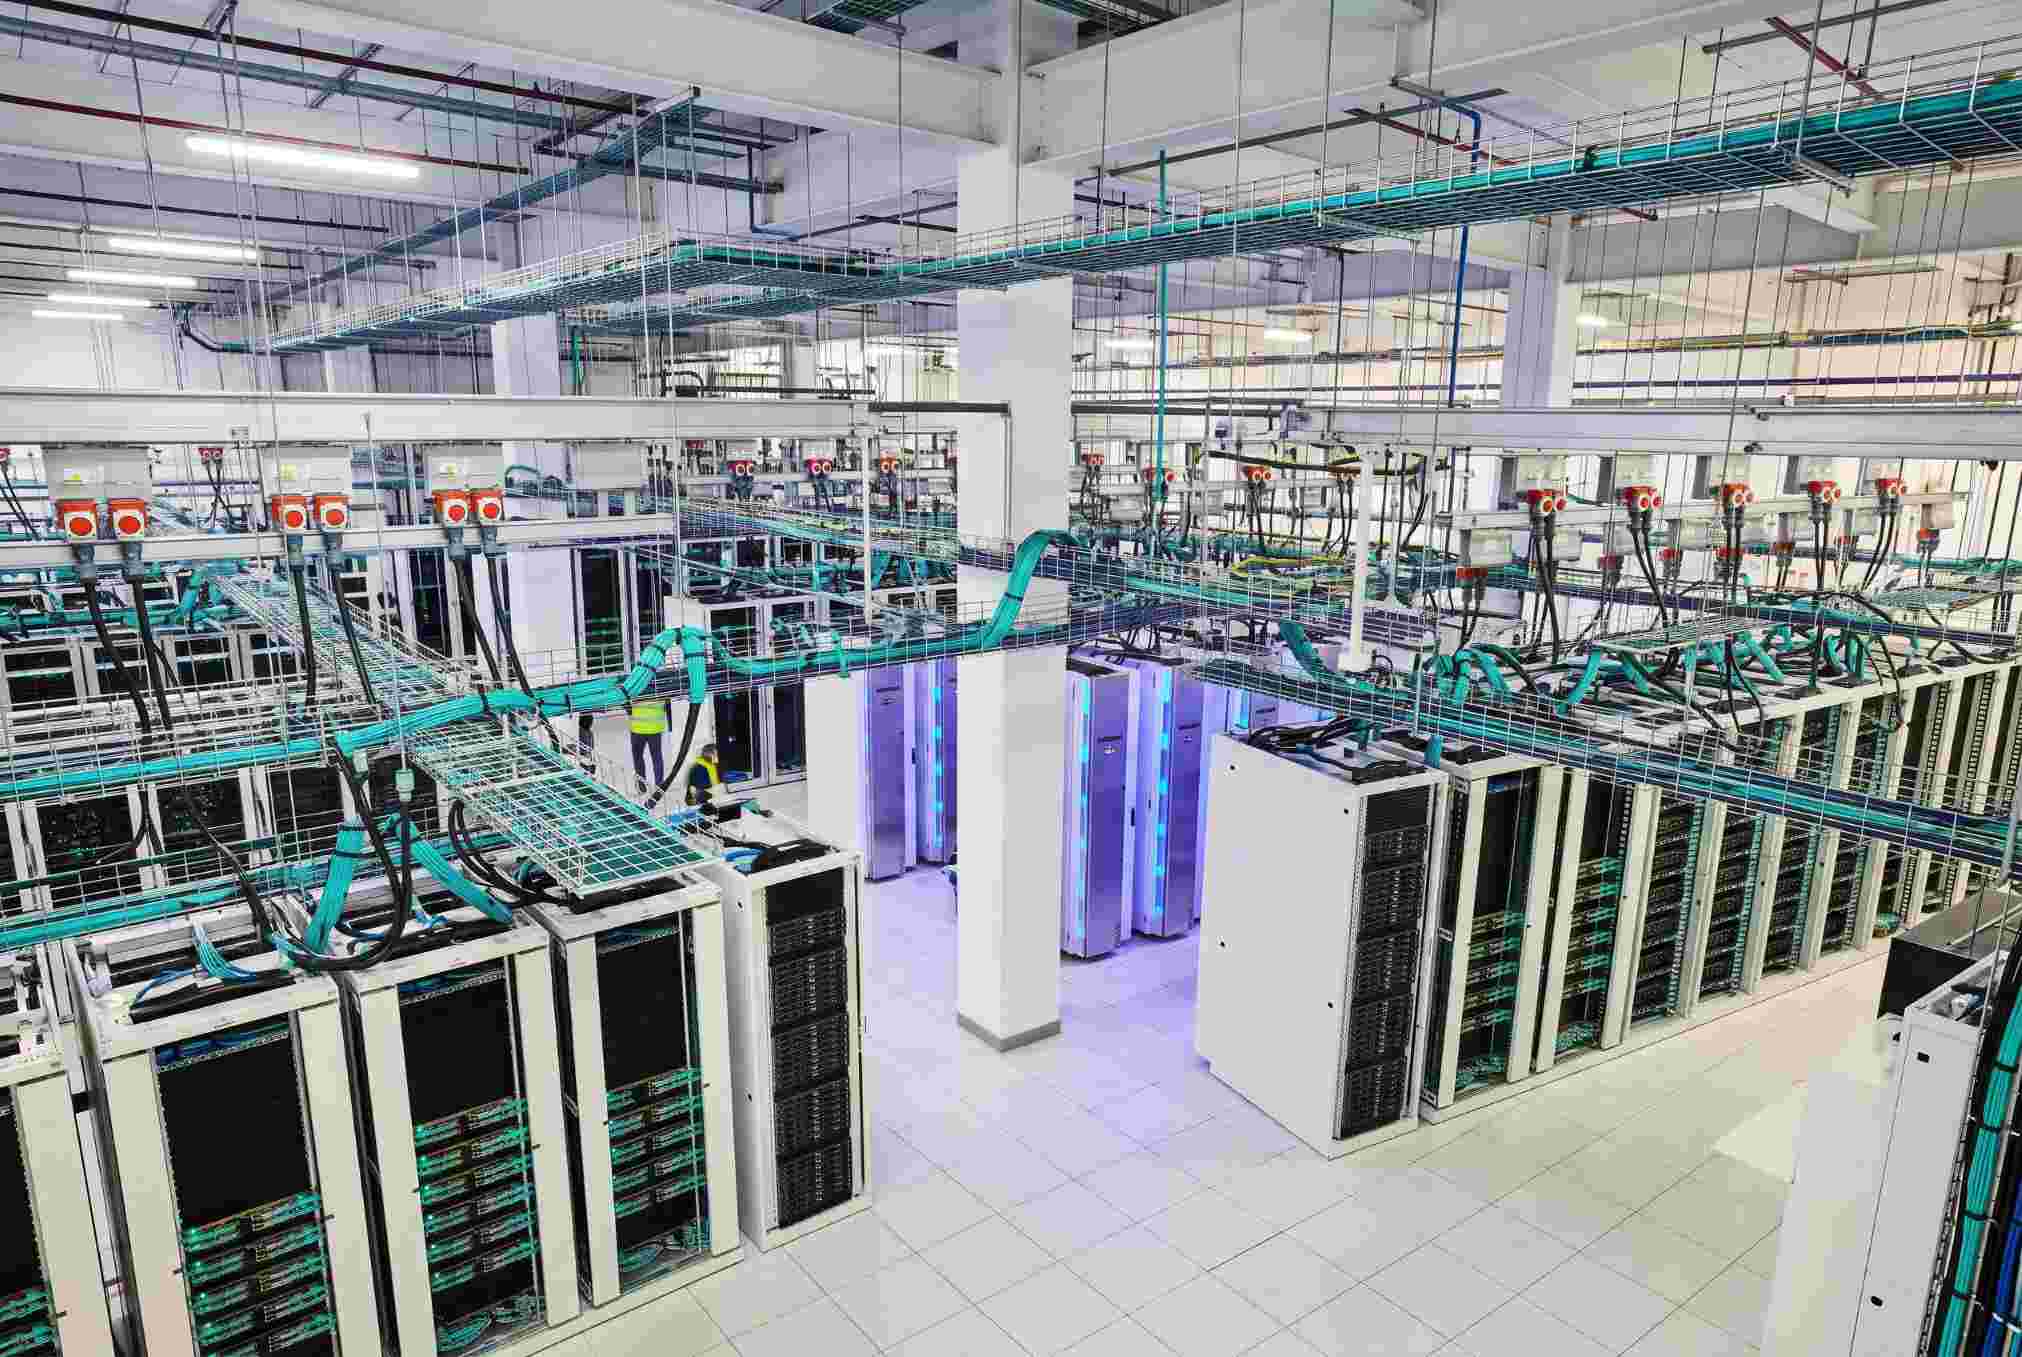
OCP Global Summit 2026: Agents, 800 Volts and a Warning on Heat
The open hardware community’s flagship week produced a 256-CPU rack built for AI agents, a new inference accelerator, an 800-volt AI factory already under construction and a cooling paper with a blunt message for all of them: the industry adopts a new method only after the old one fails, and it pays for the delay.
At the 2026 OCP Global Summit in San Jose, the open hardware community moved its focus to readiness. The specifications, supply chains and skills for the next infrastructure transition are being built now, before a chip or a power grid makes them mandatory.
The CPU Returns to the Main Stage
The clearest sign of that shift came from the processors that feed AI accelerators rather than the accelerators themselves. Arm’s Mohamed Awad told the Monday keynote audience that AI agents, which he described as software that automates a person’s intent, now run as dedicated virtual machines with their own CPUs, memory and security isolation.
“An agent is just a virtual user. A virtual user who never sleeps,” Awad said.
Awad split the market into three CPU jobs: the head node feeding the accelerator, the cloud-native CPU serving users and managing infrastructure, and the agentic CPU acting as the virtual user. Arm published a white paper on CPU performance for agentic AI, developed with Fujitsu, Meta and OpenAI, and asked the OCP community to treat it as a starting point.
NVIDIA’s Ian Buck answered with hardware. The company’s Vera CPU rack, an MGX design holding 256 liquid-cooled CPUs, is now shipping, and NVIDIA contributed its third-generation MGX 1.2 rack architecture to OCP, down to the compute tray, busbar and quick disconnects. Buck said NVIDIA designed Vera for single-threaded speed because a gigawatt-scale factory of GPUs should not wait on a CPU.
AMD’s Lisa Su made the same point from the other direction, introducing Helion, an OCP-based rack for agentic AI that customers can configure CPU-only or with GPUs, with partner systems planned for November.
Accelerators still had their moment. Microsoft unveiled Maia 300, an inference accelerator the company says delivers up to 7x the rack-scale token throughput of Maia 200, with multi-gigawatt deployments planned from 2027.
Scale-Up Ethernet and the Life of Copper
Broadcom’s Asad Khamisy gave the summit its most direct example of an industry extending an incumbent technology rather than replacing it. Five or more hyperscalers now run Ethernet scale-up networks in production, he said, and the OCP Ethernet for Scale-Up Networking effort, ESUN, has grown to more than 175 organizations since its launch at last year’s summit.
On cabling, Khamisy said new modulation can double bandwidth inside a rack while holding copper’s 2-meter reach, which he described as extending the life of copper in the rack. Beyond a thousand XPUs, he said, operators are moving to hybrid designs with copper inside the rack and optics across racks. Microsoft’s Reynold D’Sa pointed to the Optical Compute Interconnect MSA, the first optical specification for multi-rack scale-up systems.
Power Climbs to 800 Volts
Power delivery produced four new specifications in a single week. Buck said the first 800-volt DC AI factory, built by Visionbay on the OCP standard now in development, cuts copper use by about 45% and scales from today’s 100-kilowatt racks toward 1 megawatt. Microsoft contributed its Mt. Diablo 800-volt architecture, which separates power conversion from the compute rack, to OCP at versions 0.7 and 1.0, and D’Sa said the company is working with utilities on a common grid-interface specification released last month.
Google, Meta, Microsoft and NVIDIA published an OCP Grid Resilience Specification that targets restoring near-full load within two seconds of a grid disturbance. Meta described its Prometheus cluster in Ohio, spanning more than 30 structures, and said prefabricated fabric buildings can bring capacity online in three to five months. OCP CEO George Tchaparian said the summit drew roughly 15,000 attendees with a 3,000-person waitlist, and the foundation expects more than 700 member organizations by year-end.
The Paper That Names the Pattern
Each of those announcements reads differently against “Thermal Boundaries in AI Infrastructure,” the 104-page paper OCP published on Oct. 12. Its authors, from Promersion, Oracle, Meta and Avayla, name the dynamic that governs cooling transitions: a new method is adopted only when the current one can no longer do the job, because each new method brings a dependency the ecosystem has good reason to defer. The paper calls this the least-disruption law.
The cost of that deferral has a name, too. When air cooling hit its physics limit on the hottest accelerators, the paper says, “only a thin layer of downstream vendors was ready for it,” and the supply of cold plates, manifolds and coolant distribution units fell short. The authors call the resulting bill “preparation debt.”
Single-phase cold plate has a physics limit of its own, projected near 4,000 watts for a reticle-class die, and the paper notes that frontier package power doubles roughly every two years. The authors’ answer is not a successor technology but a toolbox: air, cold plate, immersion, two-phase methods and microfluidics kept ready, interoperable and matched to the heat, the site and the moment.
The keynotes supplied the toolbox in practice. Microsoft’s third-generation Mt. Atlas heat exchanger nearly doubles cooling capacity in the same footprint, and the company now runs multiple independent water loops at different temperatures for a mixed fleet of liquid-cooled and air-cooled racks. NVIDIA’s MGX 1.2 contribution standardizes flow rates and quick disconnects so that OCP members can build compatible parts, Buck said, and he said assembly of the Vera Rubin compute tray dropped from 90 minutes to one minute.
The TechArena Take
The thermal paper closes with a line that could serve as the summit’s thesis: “Air cooling is finishing. Liquid cooling is just beginning. No single method wins, and the only real choice is to be ready for all of them.”
We read this year’s OCP Global Summit as the week the community put the paper’s advice into practice. The 800-volt specification, the grid resilience specification, ESUN and the OCI MSA all arrived before the parts that depend on them have shipped at volume. That timing is the readiness the paper asks for.
The paper also names the gap that the keynotes left open. Commissioning, the step between building a multi-technology thermal system and trusting it with production load, now binds schedules as tightly as physics binds the chip, and the paper says no single vendor owns it. Operators should expect the next round of OCP work to land there, at the seam between the server and the building, where the paper says the lasting value sits. The companies that prepare that seam now will deploy when the next wall arrives. The rest will scramble, and the paper has already shown what the scramble costs.