Welcome to
the Forum
Engage innovators and practitioners on the edge of technology advancement.


TechArena Launches Mentoring to Fill the Grace Hopper Gap
I founded TechArena on a simple belief: the best advancements in technology come from a wider range of voices than our industry usually puts on stage. That’s why this month’s cancelation of the Grace Hopper conference hit so hard. For more than 30 years, Grace Hopper has been where women in computing found mentors, sponsors, and their first real sense that they belonged in this industry. Grace Hopper also leaned into allyship, itself building the widest expanse possible for connection and community.
Anyone who has sat in a room or attended a conference where no one resembles you knows how important this is. Its loss is more than a canceled event. It leaves a hole in the pipeline at the exact moment the leaders of the AI era are being chosen. I’ve spent my career in this industry, from Intel and Micron, to building TechArena, and I know how much of career advancement happens through mentors, allies, champions, and people willing to tell you the unwritten rules. When the rooms where that happens disappear, talented people stall.
That’s why we’re launching TechArena Advisory mentoring now with a sprint of speed-round sessions. This program pairs emerging leaders with our advisors and leaders from our network. Operators who have run businesses, launched platforms, and made the hard calls at the highest levels of tech are dedicating their availability to engage. Our Advisors are collectively grateful and humbled by the collective outpouring of participation from executives who have shaped our industry for decades.
Anyone who is seeking help with connection or earned insight can simply visit our website and sign up for an available slot between November 2nd and 4th. Lakecia Gunter and Raejeanne Skillern, our TechArena Advisors who were planning to teach at Grace Hopper this year, alongside VSORA Chair Sandra Rivera, will also be delivering their course as planned online for all to access. The course is titled, "From Impact to Influence: How Women in Tech Can Prepare for Board Roles." And we're offering any other presenters the opportunity to host sessions on our platform as well.
This program comes from the same commitment to talent across all vectors of inclusion that shapes whose voices we publish, who we put on stage, and how we build our own team. If we want an AI era that works for everyone (and we certainly do), the people building it have to come from everywhere, and that work can’t pause because a conference did.
Graid Technology Takes Aim at the Inference Memory Wall
Storage spent most of the last two decades as the part of the server nobody had to think about very hard. It was evaluated on capacity, reliability and cost per gigabyte, and the interesting engineering happened elsewhere. That is not where the industry is today. As deployments shift from training to inference, the question of where a model keeps its working context has become a performance problem with real money attached to it. I recently sat down with Garrett McKibben, senior director of technical marketing at Graid Technology, to talk about what inference workloads are doing to the memory and storage hierarchy. Garrett and I have been talking about the blending of that hierarchy for a long time, and this conversation was the first one where the economics of it felt concrete.
The One Lane Bridge
Graid Technology has been in market for about five or six years, built around a premise that sounds almost contrarian: remove the RAID controller entirely, let host memory talk directly to the SSDs, and accelerate the I/O path with the GPU. The reason comes down to arithmetic.
“Any single PCIe by 16 Gen 4 was limited to 30 gigs of throughput. Gen 5 is limited to 60 gigs of throughput,” Garrett said. “The analogy we like to use is you've got a four lane highway and to get to your storage, you have to go down to a one lane bridge.”
Buyers have invested heavily in NVMe performance, then sipped it through what he called a tiny coffee straw. That mismatch was the company’s original opening. It has since expanded. The company acquired the VROC assets from Intel roughly a year ago, with VROC by Graid Technology arriving in the coming months. Now it is pointing its efforts toward applying the same I/O thinking from its founding to agentic AI and KV cache.
The Economics of Remembering
As attention shifts from training to inference, the gating factor is not compute. Garrett pointed instead at capacity and the cost per gigabyte across the hierarchy. HBM on a Blackwell part tops out near 180 gigabytes at $50 to $80 per gigabyte. System DRAM improves the economics at $5 to $8 per gigabyte but remains finite. NVMe runs $0.08 to $0.12 per gigabyte with effectively unbounded capacity.
The instinct when a model runs out of room for its KV cache is to add GPU memory. Garrett’s math says that path closes quickly.
“With that limited amount of HBM, in our calculations, you run out of concurrent users after about three or four users,” he said. “As much as maybe NVIDIA would love each of us to go buy a new Blackwell 200 for every three users, it’s not feasible.”
Fetch Versus Recompute
The test for any storage tier in this role is simple to state and harder to satisfy. A GPU that loses its context can always recompute it, and it does so quickly. Storage only earns its place when retrieval beats recalculation.
“Fundamentally, fetch has to be faster than recompute,” Garrett said. “If it takes longer for the GPU to go fetch it…than it takes to compute, then there’s no value.”
Graid Technology published results measuring exactly that. With no KV Cache, recomputation took 29.5 seconds; adding MD RAID raised it to 36.6 seconds. SupremeRAID reduced the KV-cache retrieval path to 9 seconds—3.2x faster than recomputing the context. Garrett was careful not to oversell the finding, noting it holds in that particular scenario rather than every case, but the direction is the point: with an unconstrained link to NVMe and long context windows, fetching wins.
The GPU-side approach costs less than most people assume. The software-only version runs on the GPUs already in the box, consuming roughly 4 percent of capacity, about six streaming multiprocessors, and releasing them the moment the I/O completes. That leaves the CPU free for the applications it is increasingly responsible for orchestrating.
What Rack Scale Changes
The shift from components to rack-level systems makes the storage question harder rather than easier. A request may be initiated on one GPU and serviced elsewhere, which means the context has to be findable across the rack or the pod without adding back the latency the design was meant to remove. Graid Technology is working with open source frameworks including LMCache and Mooncake toward a single namespace that can meet those latency requirements.
Garrett framed why any of this matters with a simple metaphor. He compared a GPU without its KV cache to walking into a room and forgetting why you went in, then having to retrace your steps. With agentic workloads running for hours or days, that retracing is not a minor inefficiency.
“There’s a difference between having them fully utilized recalculating the same thing time and time again versus retrieving it and then moving to the next step,” he said. “It’s no longer about FLOPS. It's about enabling your engineers or your users to get results through their agents.”
The TechArena Take
The blending of the memory and storage hierarchy has been a talking point for the better part of a decade. KV cache overflow now gives it a number attached to it. Fetch versus recompute is a clean test, and it changes the buying conversation: a team with a system that retrieves context instead of recomputing it is not saving on storage, it is recovering GPU cycles it already paid for. That is a materially different business case, and it lands with a different set of decision makers.
The open question is rack scale. Single-server results are encouraging, but inference is becoming a distributed problem, and locating a given KV cache across a pod without reintroducing latency remains unsolved. We’ll be watching which approaches holds up as the unit of deployment keeps getting bigger.
AI Inference is Changing the Entire Data Center
The first generation of AI infrastructure was built primarily for training: moving enormous datasets fast enough to keep GPUs productive through large, compute-intensive runs. Production inference introduces a different set of demands. Time to first token, token throughput, latency, tokens per watt, and customer experience all influence how operators measure success. Agentic AI adds another layer of complexity, with longer, multistep workflows that generate and reuse growing amounts of context.
At Yotta 2026, TechArena CEO and founder Allyson Klein moderated two panels exploring these implications across AI infrastructure. The first, “The Inference Storage Problem: Rethinking Data Architecture for AI at Scale,” examined the demands inference and agentic workloads place on compute, networking, memory, and storage. It brought together Marc Austin, CEO and co-founder of Hedgehog; Sam Clarke, vice president of neocloud and AI business development at VDURA; Angel Camacho, director of product marketing at Western Digital; and Betsy Chernoff, principal AI product marketing manager at WEKA.
The second panel, “Tokens per Watt: Efficiency as the Fastest Path to AI Capacity,” extended the conversation to power, cooling, and facility infrastructure. Chernoff returned, joined by Peter Panfil of Vertiv and Sean Corcoran, Vice President of Sales for PowerOne at Airsys. They explored how increasingly dynamic AI workloads affect power demand, thermal management, and the physical limits of data center capacity.
Together, the discussions revealed a common challenge: delivering more useful AI output requires coordinating resources across the entire infrastructure stack. As inference becomes a larger share of AI workloads, operators must consider how compute, memory, storage, networking, power, and cooling work together to determine performance, efficiency, and capacity. From the conversations, several key insights emerged.
Inference Changes What Infrastructure Needs to Optimize For
Operators increasingly need infrastructure that serves training and inference simultaneously. While training prioritizes completing large compute jobs and keeping GPUs supplied with data, inference introduces new performance requirements. Distributed inference also places greater demands on networking and data movement as pilots scale into production. Angel noted that pilots can comfortably hold large amounts of data in RAM, but that approach becomes prohibitively expensive as applications expand to hundreds or thousands of users.
GPU utilization can also be misleading. An accelerator may remain highly utilized while repeating computations unnecessarily, so operators need to evaluate useful output, response times, and the energy required to generate each token.
“Our job is really to make sure that the GPUs...keep working, keep the beast fed, and also on the inference side, make sure they’re not doing the work twice,” Sam said.
These changing workloads also affect facility infrastructure. Peter described GPU demand shifting rapidly between relatively low and high loads. Electrical systems experience those fluctuations immediately, while thermal systems respond to the resulting heat with a delay. Power and cooling must therefore adapt to increasingly dynamic compute requirements.
“This is not our father’s cloud world anymore,” Peter said. “This is a dynamic world in which the systems are interdependent.”
Inference efficiency, in other words, runs from the application through compute, memory, storage, and networking, all the way to power delivery and heat rejection.
Keeping GPUs Productive Requires Managing Data and Context Intelligently
Agentic AI makes context management an increasingly important infrastructure challenge: agents perform multistep tasks that depend on information generated earlier in the workflow, requiring systems to retain and retrieve growing amounts of context. The key-value (KV) cache preserves this information so models can reuse previous computations.
“Context matters. It’s important that our agents remember what we’ve been doing,” Angel said. “Otherwise, we will have to recompute all that we’ve been doing, spending GPU time.”
High-bandwidth memory (HBM) provides fast access to data but remains expensive and capacity-constrained. Betsy described how storage can extend the memory hierarchy by holding KV-cache data that doesn’t need to remain in HBM, then returning it when required. “We were able to take from high bandwidth memory all of this cache and hold it on storage and then send it back to the GPUs as quick as DRAM or as quick as the system needs,” she said.
This approach allows frequently accessed context to remain close to the GPU while less urgent information moves to lower-cost storage tiers. It also helps reduce unnecessary recomputation, freeing accelerator capacity for new work.
Betsy emphasized that different stages of inference place different demands on compute and memory. Prefill is compute-intensive, while decoding depends more heavily on memory bandwidth. As context windows expand and agentic workflows become more complex, managing data placement across memory and storage becomes increasingly important.
The implications extend to existing GPU fleets. Software-defined infrastructure, GPU mobility, fewer unnecessary data copies, and efficient offloading can help operators extract more useful work from deployed accelerators.
Every unnecessary GPU cycle consumes power and limits available compute capacity, making effective context management critical to inference performance and infrastructure economics.
The Bottleneck Is Moving Beyond the GPU
As inference workloads become more complex, networking plays a greater role in bridging compute with the memory and storage resources it needs. Marc described the network as a bus connecting different levels of the memory hierarchy, from on-chip SRAM to flash storage.
That relationship has implications for network topology too. Training and inference may require different architectures, particularly as storage becomes more directly involved in moving KV-cache data. Disaggregated inference adds another consideration, allowing different stages of a workload to run on resources suited to their computational requirements, while latency-sensitive applications may also drive infrastructure closer to end users.
The constraints also extend beyond data movement. Higher rack densities have increased the importance of thermal management, with direct-to-chip liquid cooling becoming central to supporting more powerful accelerators. Air cooling still has a role, making hybrid approaches important as facilities accommodate a wider range of equipment.
These decisions require closer coordination between mechanical, electrical, and compute teams, since cooling architecture affects facility power consumption and how much capacity remains available for IT equipment.
“It has to be the whole architecture of the data center,” Sean said, describing a design approach that extends “from the chiller to the chip.”
As accelerators become more powerful, infrastructure design increasingly determines how effectively their capabilities can be used.
Optimize the System, Not Just Its Components
Enhancing the performance of an individual component doesn’t necessarily improve the efficiency of the entire AI infrastructure system. Decisions about compute, memory, networking, storage, power, and cooling need to account for how those resources interact before deployment.
“The biggest piece is to think strategically around how you architect across your infrastructure,” Betsy said. “Certainly starting from the GPU, but in addition to that, you have to consider networking [and] storage...well before you start to build.”
The same principle applies to facility infrastructure. “It’s a system. It’s got to be treated like a system,” Peter said. Optimizing individual subsystems can improve their performance without delivering corresponding gains across the facility.
The growing importance of storage illustrates how quickly infrastructure priorities can shift. Betsy noted that roughly a year and a half earlier, storage received little attention in AI infrastructure discussions because it represented a relatively small share of the bill of materials. Today, its role in supporting inference makes it a much more consequential architectural consideration. The challenge is to evaluate design decisions by their effects on overall performance, capacity, and efficiency, rather than the capabilities of any single component.
New Workloads Require New Measures of Efficiency
As inference becomes a larger share of AI workloads, operators need metrics that connect infrastructure performance to useful output.
Angel emphasized the importance of defining success before deciding what to measure. “First of all, metrics. You cannot find success if you don’t measure it,” he said. “You need to first establish what you really want to do. What is the outcome that you are looking for?”
That principle extends to facility infrastructure, where conventional efficiency metrics don’t always capture how much useful AI work a data center produces. Peter advocated measuring tokens per second per watt to connect computational throughput with energy efficiency.
Sean introduced power compute effectiveness (PCE), a metric examining how effectively provisioned building power supports provisioned IT load. At data center scale, even modest improvements in electrical and thermal efficiency can translate into meaningful capacity and cost benefits.
The shift is reaching individual infrastructure components, too. Betsy noted that WEKA’s benchmarks now include tokens per watt per second, reflecting growing interest in evaluating storage through its contribution to overall AI efficiency.
Together, these measures help operators connect workload performance, infrastructure utilization, and facility economics.
The TechArena Take: Start With the Outcome, Then Architect Backward
The central lesson from both panels is that AI infrastructure design must begin with the workload and the outcomes operators need to achieve. Establish the metrics that define success, then architect backward across compute, memory, networking, storage, power, and cooling.
Peter explained the risk of approaching those decisions independently: “If we treat it as the individual subcomponents, we might be able to optimize the performance on one of those subcomponents, but we’re not going to optimize the performance out of the system.”
As inference and agentic AI reshape infrastructure requirements, the ability to coordinate resources across the entire data center will increasingly determine how much useful work operators can deliver from their available capacity. In the inference era, the data center is no longer just the place where AI runs, but part of the AI system itself.
The Memory Problem Is Geometry: Ventiva on Cooling for Local AI
As AI hardware evolves, bringing memory closer to compute has become a critical design priority. Carl Schlachte, chairman, president and CEO of Ventiva, calls it the investment thesis of the decade. But it requires rethinking the physical space occupied by conventional cooling systems.
Carl returned to In the Arena with TechArena’s Allyson Klein at the 2026 AI Infra Summit, following a conversation last year, when he previewed a significant demonstration planned for CES 2026.
Ventiva develops thermal management technology for applications ranging from consumer electronics to data centers. Its solid-state airflow technology offers a highly modular cooling solution, creating new opportunities for component placement and system design.
Rethinking Laptop Cooling
Conventional laptop motherboards typically accommodate two fans measuring approximately 55 millimeters in diameter, with semicircular cutouts on either side of the board. This configuration consumes valuable space that could otherwise support memory, connectivity, and other components.
At CES 2026, Ventiva demonstrated an alternative architecture featuring a rectangular motherboard with cooling concentrated toward the back. The design delivered comparable thermal performance to a conventional fan-cooled laptop while operating silently, with no moving parts.
The improvement extended beyond acoustics and thermal performance: eliminating the fan cutouts also freed motherboard space for additional components. For Ventiva, this represented a shift from solving a thermal management challenge to enabling new possibilities in system architecture.
Generating Airflow Without Moving Parts
Ventiva uses electrohydrodynamic (EHD) flow to generate airflow without mechanical fans. Its compact rectangular ionic cooling modules recover the physical board space used by conventional fans. This gives designers the ability to add more memory, storage, battery capacity, or other new components. For local AI, that flexibility helps address a critical design constraint: finding room for more memory closer to the processor.
Why Local AI Depends on Memory Proximity
The growing importance of inference and agentic AI is changing how system architects think about memory capacity, bandwidth, and physical placement. Carl argued that many major advances in AI infrastructure, including optical interconnects and new communication architectures, address the same underlying challenge: reducing the distance and communication overhead between memory and compute.
For local inference, that constraint becomes especially significant. According to Carl, memory supporting effective on-device AI needs to sit approximately 15 to 25 millimeters from the processor complex. Conventional laptop fans compete for that space, particularly as CPU and GPU packages become larger and more power-intensive.
But processor specifications alone don't tell the full story. A laptop may offer substantial AI compute capability, measured in trillions of operations per second (TOPS), while its practical inference performance also depends on memory capacity, bandwidth, and how efficiently it can access model data.
Ventiva’s ultra-thin modular cooling solution creates room to position additional memory closer to the processor, potentially supporting larger models without increasing the device's external dimensions.
Carl sees this as an opportunity to run more AI workloads locally rather than relying exclusively on centralized infrastructure: “You can build a data center $3,000 at a time if you did it the right way.”
The idea is to equip individual machines with sufficient compute and memory to run appropriately sized language models. Rather than sending every inference request to the cloud, users could execute suitable workloads directly on their devices, reserving remote resources for more demanding tasks.
Ventiva doesn't replace established thermal technologies such as vapor chambers or heat pipes. Its solid-state airflow works alongside them, potentially improving heat removal while freeing space for other components.
The economics could be equally significant. Local inference can reduce recurring cloud computing costs by using hardware already deployed to end users. As more workloads become practical on client devices, organizations may be able to handle routine AI tasks without paying for remote compute on every request.
From Thermal Component to Platform Architecture
Carl described a broader change in how Ventiva engages with laptop manufacturers. Rather than discussing cooling as an isolated subsystem, the company is increasingly involved in conversations about motherboard layout and overall platform design.
A rectangular motherboard can simplify manufacturing by eliminating large cutouts associated with conventional fan assemblies. It may also allow more direct routing between I/O components and the processor, reducing the need for signal repeaters and potentially lowering system costs.
By changing where cooling hardware sits, manufacturers gain greater flexibility in how they allocate space, route connections, and integrate memory.
Carl also expects local AI capabilities to influence laptop purchasing and replacement cycles. As devices handle more inference workloads, buyers may place greater value on performance and longevity. This could challenge traditional three-year refresh cycles and the role of laptops as terminals for cloud-based applications.
The external form factor may remain familiar. Carl expects the clamshell design to persist, with more substantial changes occurring inside the chassis.
Addressing the Thermal Orphans in AI Servers
Ventiva’s solid-state cooling technology also has applications in data centers. As AI server power densities increase, CPUs, GPUs, and high-bandwidth memory increasingly rely on cold plates and direct-to-chip liquid cooling. This transition reduces the need for conventional fans around high-power processors, but creates challenges for components that still depend on airflow.
In traditional server architectures, air moves from the front of the chassis toward the rear, absorbing heat as it passes through the system. Reducing fan capacity can leave downstream components with both less airflow and higher inlet temperatures. Carl calls these components thermal orphans: boot-optimized storage, SSDs, and other devices toward the rear of the server that may not justify dedicated liquid cooling but still require effective thermal management.
Failures in these components can affect the availability of the entire system. Carl noted that even a 5% failure rate in rear-mounted storage can undermine overall server availability, regardless of the performance of the GPUs at the front.
Ventiva’s approach delivers localized airflow directly to these underserved devices without requiring major changes to existing hardware designs. Form factor is particularly important, as manufacturers of rear-mounted cards are reluctant to redesign established mechanical configurations. A cooling solution that fits within existing dimensions and delivers a 5% to 10% improvement could offer a compelling advantage.
In the server, the goal is to supplement liquid cooling, not replace it. Targeted solid-state ionic cooling modules can operate alongside cold plates, addressing thermal requirements that direct-to-chip systems do not cover.
Carl described initial skepticism from thermal engineers accustomed to designing around mechanical fans, but once they saw airflow delivered into previously impractical locations, the discussion shifted toward additional applications.
Bringing Solid-State Cooling to the Data Center
Ventiva's data center business is focused on targeted improvements rather than replacing established cooling infrastructure. Carl identified rear-of-rack components as a practical entry point, since these devices can often be replaced independently of broader server or facility upgrade cycles. This creates an opportunity to improve thermal performance without waiting for the next platform generation.
A replacement card that operates more reliably or delivers better performance within the same mechanical envelope could justify a price premium, particularly when component failures threaten server availability. For Ventiva, this offers a potentially faster path to adoption than integration into new server architectures requiring multiyear design and qualification cycles.
The TechArena Take
Ventiva's technology demonstrates how thermal management decisions increasingly influence AI system architecture.
Using ultra-thin cooling modules in laptops can free motherboard space for memory closer to the processor, addressing a critical constraint on local inference. In data centers, targeted solid-state airflow can support components that remain dependent on air even as high-power processors transition to liquid cooling.
The broader opportunity is to give system designers greater freedom to allocate space according to computational requirements rather than the dimensions of conventional cooling hardware.
The implications for local AI are particularly significant. As more inference and agentic workloads become viable on client devices, AI infrastructure could become increasingly distributed across enterprise laptops and other endpoints.
Realizing that potential requires manufacturers to consider motherboard layouts, memory integration, and thermal architecture together. Ventiva's ongoing discussions with OEMs suggest that this design conversation is already underway.
Listen to the full In the Arena episode featuring Carl Schlachte.
Agentic AI Is an Open Systems Challenge...and Opportunity
OCP Global Summit week opened for me with brunch and a question that has percolated in my mind all year: What does it take to run AI agents in production? MiTAC Computing hosted its Executive Tech Forum on Monday morning , and I had the pleasure of moderating a panel with Intel, SK hynix, Solidigm and MiTAC under the title Powering the Agentic Era: Compute, Memory, Storage and Scale.
Each company took a few minutes to make the case for the layer it builds. Assembled end to end, the four presentations delivered a comprehensive view on how innovation is accelerating across the system and the data center. Only in working together can we solve this open systems challenge that is becoming more urgent. Agentic AI changes the demand on every part of a rack or pod level platform at once, and the companies that treat the challenge as a single design problem will deliver to true operator requirements. Here is more of what I took from the room.
From Training Once to Agents All the Time
SK hynix America’s Vis Valluri, senior director of industry intelligence, set the frame with a simple progression. Training happens once. Inference runs in real time. Agentic AI runs all the time. He made his claim citing data from OpenRouter and a16z showing that agents overtook humans as the main source of token traffic early this year, with token usage up 14 times since.
The mechanics of agentic workflows explain this surge precisely. A regular inference request makes one pass through prefill and decode and returns a response. Simple and linear! An agent works in a loop: prefill, decode, call a tool, observe the result, then fold that result back into the context for another round of prefill. The KV cache grows with every turn. Valluri put the consequence in one number. More than 85% of agent tokens come from cached prompts, which means agents spend most of their time rereading context they already hold.
That single behavior sets up everything the other speakers had to say and defined a challenge across compute, memory and storage working tightly in tandem.
Compute Sits at the Foundation
Gary Brown of Intel opened his segment with a message that compute acts as a foundation to memory, storage, broader infrastructure (don’t forget the network!). As the resident CPU builder, he made the case for compute with throughput data.
Brown showed Intel Xeon 6 against competing CPU instances on healthcare agent workloads covering reasoning, security and control operations, laying out performance benchmarks of the alternative platforms. And while Intel was seeking a performance leadership win, the bigger takeaway for me is that in the agentic era, core functions of workload management matter a lot... and these are the realm of CPUs.
Intel’s own recent announcements argue that as AI turns agentic, the bottleneck moves toward orchestration, concurrency and data movement. Brown’s portfolio slide spread agentic scale across what Intel calls the intelligence and execution layers, with GPUs handling prefill. An agent spends much of its life between model calls, running tools and checking results. Someone has to schedule all of that, and the processor is a natural orchestrator.
Memory Gets New Floors
Valluri took Intel’s view and built from it with a memory centric perspective on the same challenge. SK Hynix sees the hierarchy being rebuilt with new tiers that fill the gaps between SRAM, HBM, DRAM and SSD. He laid them out from fastest to largest: a G0.5 tier of 3D-stacked DRAM with near-SRAM speed, HBM at G1, a G1.5 tier of stacked flash called HBF offering roughly 1 TB at terabit-per-second scale, conventional DRAM, a G2.5 tier of CXL-pooled memory in the multi-terabyte range, and SSD beneath it all.
The demand driver he chose was personal agents, pointing to Meta’s personal agent running on Muse Spark. This agent remembers details you mentioned once, keeps working after you close the app and runs in a dedicated cloud VM for each user. Persistent context that grows per user means more memory at every tier. When I think about the scale of that arithmetic across a large user base, the new tiers look like necessities rather than options, and the importance of memory and storage innovation argue to take center stage as the existential challenge of agentic performance.
The Price of a Prompt
So where was storage in all of this? Enter Solidigm’s Ace Stryker. He made the bluntest case of the discussion, using simple math as his tool. He started with a 14-word question: what’s a cool bird I might see when I’m in San Jose next week? That prompt is 18 tokens. The model processes far more. System prompt and policies account for 10,000 tokens, retrieval for 15,000, tool schemas for 5,000 and conversation history for 12,000. The total reaches 42,018 tokens. My guess is, in reality, we could argue it being even higher.
And... that context has to live somewhere. For one user making one request, Stryker calculated about 13.1 GB of KV cache, scaled from NVIDIA’s figure of 40 GB at 128K tokens for Llama 3 70B at FP16. Multiply by concurrent users and sessions and the memory bill scales quickly.
Solidigm’s answer to drive efficiency into the equation is to transfer that model state on SSD and restore it rather than recompute it. In work with Metrum AI, retaining KV cache on a Solidigm D7-PS1010 cut time to first token from 31 seconds to 2.8 seconds in a single-user sports archive scenario. In a separate video analytics test, pairing KV cache with DiskANN retrieval lifted queries per second by 14%, from 2,071 to 2,371 at 1,024 query threads. Stryker flagged these as separate results rather than a combined speedup, and I will repeat that caution here. He closed on a line that deserves a spot on every infrastructure budget review: every token has a resource cost, and every resource has a dollar cost.
Rack-Scale Reality
MiTAC Computing ’s Raymond Huang took the conversation from cutting edge silicon innovation to system delivery at scale, under the banner, “Where AI Power Meets Rack-Level Scalability.” Silicon only matters once it ships as a working system, and his slides were about that last mile and connecting acute operator requirements in a couture fashion with bespoke systems leveraging industry standards.
MiTAC cited more than 30 MW of rack-scale manufacturing power in 2026, capacity for 5,000 racks per month, networking up to 800 Gb/s and power readiness from 480 VAC up to 800 VDC. The MiTAC California footprint anchors this: It's Newark site features an NPI direct liquid-cooling facility, while San Jose provides dedicated liquid-cooling manufacturing. A mega-scale, six-building campus in Fremont further strengthens the company’s ability to design, validate, and produce advanced computing solutions. From PCB and motherboard design to barebone, systems and complete AI clusters, MiTAC delivers vertically integrated, in-house engineering that accelerates time to market and ensures end-to-end quality. On the product side, Huang showed a 52U high-density liquid-cooled rack, including a direct liquid-cooled MI355X GPU configuration, and a 256-GPU cluster example with in-row coolant distribution and a separate aggregation switch rack.
MiTAC pairs the hardware with open firmware and management software called MiOBMC™, MiOPF™ and MiCoreView™, and with ecosystem partners including DDN, Rafay and Canonical Ubuntu. A partnership with Tonomia targets modular AI data centers. Its Diamond Cooling approach aims to keep token generation throttle-free at standard data center temperatures, which could trim power and cooling costs if it performs as described.
The delivery model closed the loop. US-based engineering and project management, local system and rack integration, and a build-to-inventory approach aim to shorten lead times for customers who cannot wait out a long supply chain.
The TechArena Take
From soup to nuts, one word runs through the discussion as a throughline. Agents carry context from step to step, and context is state. State has to live somewhere, and every element of infrastructure is now being asked to hold more of it, closer to the processor and for longer. SK Hynix described the tiers that hold it. Solidigm priced it in both gigs and dollars. Intel claimed the baton with the statement that the processor orchestrates it. MiTAC showed how to package it all into racks that arrive on schedule.
Run the memory math once and the stakes come into focus. A single request can carry 13.1 GB of cache, and a personal agent maintains its memory between sessions. The capacity question becomes a per-user number multiplied by a sea of agents and humans. Size up that investment, and the case for re-tiering and deeper performance tier SSD use comes into acute focus.
Capacity plans built around model size and GPU count will miss the largest cost driver in agentic deployments. Plan around the workflow and sustained memory: how large does it grow per session, how many sessions run at once, and where each piece of it should live. Operators who answer those questions across compute, memory, storage and rack design together leveraging all of the standards the OCP community provides will build agent infrastructure that scales at speed.
OCP Global Summit 2026: Agents, 800 Volts and a Warning on Heat
The open hardware community’s flagship week produced a 256-CPU rack built for AI agents, a new inference accelerator, an 800-volt AI factory already under construction and a cooling paper with a blunt message for all of them: the industry adopts a new method only after the old one fails, and it pays for the delay.
At the 2026 OCP Global Summit in San Jose, the open hardware community moved its focus to readiness. The specifications, supply chains and skills for the next infrastructure transition are being built now, before a chip or a power grid makes them mandatory.
The CPU Returns to the Main Stage
The clearest sign of that shift came from the processors that feed AI accelerators rather than the accelerators themselves. Arm’s Mohamed Awad told the Monday keynote audience that AI agents, which he described as software that automates a person’s intent, now run as dedicated virtual machines with their own CPUs, memory and security isolation.
“An agent is just a virtual user. A virtual user who never sleeps,” Awad said.
Awad split the market into three CPU jobs: the head node feeding the accelerator, the cloud-native CPU serving users and managing infrastructure, and the agentic CPU acting as the virtual user. Arm published a white paper on CPU performance for agentic AI, developed with Fujitsu, Meta and OpenAI, and asked the OCP community to treat it as a starting point.
NVIDIA’s Ian Buck answered with hardware. The company’s Vera CPU rack, an MGX design holding 256 liquid-cooled CPUs, is now shipping, and NVIDIA contributed its third-generation MGX 1.2 rack architecture to OCP, down to the compute tray, busbar and quick disconnects. Buck said NVIDIA designed Vera for single-threaded speed because a gigawatt-scale factory of GPUs should not wait on a CPU.
AMD’s Lisa Su made the same point from the other direction, introducing Helion, an OCP-based rack for agentic AI that customers can configure CPU-only or with GPUs, with partner systems planned for November.
Accelerators still had their moment. Microsoft unveiled Maia 300, an inference accelerator the company says delivers up to 7x the rack-scale token throughput of Maia 200, with multi-gigawatt deployments planned from 2027.
Scale-Up Ethernet and the Life of Copper
Broadcom’s Asad Khamisy gave the summit its most direct example of an industry extending an incumbent technology rather than replacing it. Five or more hyperscalers now run Ethernet scale-up networks in production, he said, and the OCP Ethernet for Scale-Up Networking effort, ESUN, has grown to more than 175 organizations since its launch at last year’s summit.
On cabling, Khamisy said new modulation can double bandwidth inside a rack while holding copper’s 2-meter reach, which he described as extending the life of copper in the rack. Beyond a thousand XPUs, he said, operators are moving to hybrid designs with copper inside the rack and optics across racks. Microsoft’s Reynold D’Sa pointed to the Optical Compute Interconnect MSA, the first optical specification for multi-rack scale-up systems.
Power Climbs to 800 Volts
Power delivery produced four new specifications in a single week. Buck said the first 800-volt DC AI factory, built by Visionbay on the OCP standard now in development, cuts copper use by about 45% and scales from today’s 100-kilowatt racks toward 1 megawatt. Microsoft contributed its Mt. Diablo 800-volt architecture, which separates power conversion from the compute rack, to OCP at versions 0.7 and 1.0, and D’Sa said the company is working with utilities on a common grid-interface specification released last month.
Google, Meta, Microsoft and NVIDIA published an OCP Grid Resilience Specification that targets restoring near-full load within two seconds of a grid disturbance. Meta described its Prometheus cluster in Ohio, spanning more than 30 structures, and said prefabricated fabric buildings can bring capacity online in three to five months. OCP CEO George Tchaparian said the summit drew roughly 15,000 attendees with a 3,000-person waitlist, and the foundation expects more than 700 member organizations by year-end.
The Paper That Names the Pattern
Each of those announcements reads differently against “Thermal Boundaries in AI Infrastructure,” the 104-page paper OCP published on Oct. 12. Its authors, from Promersion, Oracle, Meta and Avayla, name the dynamic that governs cooling transitions: a new method is adopted only when the current one can no longer do the job, because each new method brings a dependency the ecosystem has good reason to defer. The paper calls this the least-disruption law.
The cost of that deferral has a name, too. When air cooling hit its physics limit on the hottest accelerators, the paper says, “only a thin layer of downstream vendors was ready for it,” and the supply of cold plates, manifolds and coolant distribution units fell short. The authors call the resulting bill “preparation debt.”
Single-phase cold plate has a physics limit of its own, projected near 4,000 watts for a reticle-class die, and the paper notes that frontier package power doubles roughly every two years. The authors’ answer is not a successor technology but a toolbox: air, cold plate, immersion, two-phase methods and microfluidics kept ready, interoperable and matched to the heat, the site and the moment.
The keynotes supplied the toolbox in practice. Microsoft’s third-generation Mt. Atlas heat exchanger nearly doubles cooling capacity in the same footprint, and the company now runs multiple independent water loops at different temperatures for a mixed fleet of liquid-cooled and air-cooled racks. NVIDIA’s MGX 1.2 contribution standardizes flow rates and quick disconnects so that OCP members can build compatible parts, Buck said, and he said assembly of the Vera Rubin compute tray dropped from 90 minutes to one minute.
The TechArena Take
The thermal paper closes with a line that could serve as the summit’s thesis: “Air cooling is finishing. Liquid cooling is just beginning. No single method wins, and the only real choice is to be ready for all of them.”
We read this year’s OCP Global Summit as the week the community put the paper’s advice into practice. The 800-volt specification, the grid resilience specification, ESUN and the OCI MSA all arrived before the parts that depend on them have shipped at volume. That timing is the readiness the paper asks for.
The paper also names the gap that the keynotes left open. Commissioning, the step between building a multi-technology thermal system and trusting it with production load, now binds schedules as tightly as physics binds the chip, and the paper says no single vendor owns it. Operators should expect the next round of OCP work to land there, at the seam between the server and the building, where the paper says the lasting value sits. The companies that prepare that seam now will deploy when the next wall arrives. The rest will scramble, and the paper has already shown what the scramble costs.
Epic Semi: Why Sovereign AI Is an Infrastructure Strategy
The boundary organizations once drew around their data now has to extend to the systems that use it. Sovereign AI gives organizations a path to make those systems truly their own.
Hospitals, banks, universities, and national labs have spent decades building systems to protect sensitive data, with patient records, transaction histories, and research files secured in tightly controlled environments.
AI is now putting time-tested safeguards under pressure as organizations seek access to increasingly capable models.
This often requires entrusting proprietary material to third-party infrastructure: every prompt or document retrieved by an LLM can shift confidential information beyond the environment designed to protect it.
Sovereign AI is an approach to AI adoption that gives organizations control over their entire AI stack, including models, compute, software, orchestration, and deployment. This doesn’t merely impact where information resides, but which technologies enterprises can adopt, how they operate, and whether resources remain available as demand grows.
Sovereign AI requires control across the stack
Sovereign AI often starts with a straightforward requirement: sensitive data must remain on premises or within a specific jurisdiction. But keeping data local doesn’t automatically ensure autonomy.
Sovereignty is control across the full AI stack. If you are not owning some piece of it, then part of your intelligence is outsourced, and it is not sovereign to you.
That distinction matters because every external dependency introduces another point where an organization can lose agency. A hospital may rely on a provider’s roadmap to support clinical applications, while financial institutions can face changes in pricing or availability, and research organizations may encounter export restrictions that limit access to critical technology.
These dependencies extend beyond data storage. A company can keep its proprietary datasets on premises while relying on external systems to process them, models to interpret them, or suppliers to provide the underlying compute. Organizations therefore need to consider what happens after they secure the data:
- Who controls the model?
- Can teams inspect and tune it?
- Will the necessary equipment remain available as deployments expand?
- Can software investments survive a change in supplier strategy or export policy?
The same concern applies to future capacity. AI deployments rarely remain fixed, so organizations need confidence that the equipment supporting them will remain available as demand grows.
Otherwise, supply constraints can limit expansion, disrupt budgets, and affect long-term planning. For example, a deployment can satisfy residency requirements at launch and still create future dependencies if additional equipment becomes difficult to procure or critical software relies on a particular roadmap.
Sovereignty ensures control over where information resides and the infrastructure used to process it.
Sovereign AI changes the compute equation
Bringing the complete AI stack inside an organization only works if the infrastructure can support its workloads efficiently. For many organizations, that means reconsidering architectures modeled on hyperscale environments and GPU-dense racks, which were designed for enormous training and inference workloads.
Sovereign AI often looks different, particularly as teams adopt agentic applications that combine AI inference with substantial general-purpose computing.
Agents shuffle through multiple operations as they complete a task. They orchestrate workflows, call tools, enforce security policies, retrieve information, query databases, and generate tokens. CPUs handle many of the control-heavy steps, while AI accelerators execute the matrix operations behind model inference. Those demands can alternate throughout a single workflow as an agent moves between reasoning, retrieval, tool use, and model execution.
For sovereign AI environments, the workload mix directly affects infrastructure decisions. A platform optimized primarily for token generation can leave expensive accelerators waiting while orchestration, database queries, security checks, or other CPU-heavy operations constrain throughput. Adding more GPUs does not necessarily address those bottlenecks, either.
Overprovisioning accelerators also raises the cost of maintaining AI infrastructure. A sovereign deployment needs enough acceleration for model operations alongside the CPU capacity and memory bandwidth required to support the rest of the workflow.
Sizing each resource around actual application requirements can therefore improve utilization while keeping more of the workload within a controlled environment, so organizations can design around applications they intend to run, rather than reproducing a hyperscale architecture inside their own data centers.
Balancing compute around sovereign AI workloads
Sovereign AI infrastructure should enable mixed workloads without overprovisioning one type of compute. Epic Semi’s Contrail AIX, for example, combines general-purpose processing and AI acceleration within one platform.
Teams should always look to support the full agentic workflow within the infrastructure they control. CPUs can handle orchestration, branching, security, database operations, and tool calls while AI cores execute model workloads. A common fabric and memory pool keep both types of compute running in the same environment. For instance, Contrail AIX combines 32 performance cores with 16 AI cores connected by a shared on-chip fabric, allowing general-purpose and model operations to access a unified memory environment.
This balance also provides more flexibility as agentic applications evolve. Enterprises are still learning how production workloads distribute demand across general-purpose processing and AI acceleration. Rather than reproducing a hyperscale configuration by default, teams can size sovereign AI infrastructure around the applications they intend to run. This approach connects control over the AI stack with the practical ability to operate efficiently at scale.
Open architecture reduces long-term dependencies
Maintaining sovereignty requires isolated workflows, enforced policies, securely managed systems, and the ability to expand capacity without unnecessarily introducing new external dependencies, especially as architecture and market conditions change. Revised product roadmaps, export policy, or component availability can undermine existing investments.
Open architectures give enterprises more freedom over the technology behind their AI systems, permitting multiple vendors to develop compatible components around a shared instruction set. Teams subsequently have access to alternatives if one supplier can no longer meet their needs.
One example is RISC-V, an open instruction set architecture (ISA) used to design processors. Or, as Sherwani describes it: “RISC-V is owned by the world. Anybody can adopt it, build on it, and contribute back to it.” RISC-V International governs the specification from Switzerland, creating a shared architectural foundation beyond any single processor supplier or national jurisdiction.
The choice of architecture can also affect the longevity of investments. Organizations may spend years developing applications, optimizing software, and integrating systems, and continued access to the foundation is critical. An open ISA provides more flexibility when there are shifts in supplier strategies, availability, or other external conditions.
Openness, however, still needs to translate into deployable infrastructure, including virtualization, memory expansion, standard interfaces, secure management, and other critical capabilities for AI systems. In practice, that means pairing architectural openness with critical production server capabilities, such as full hardware virtualization, IOMMU support, and standard interfaces.
Enterprises also need a realistic path to procuring equipment, especially in regulated and geographically distributed markets. These considerations determine whether architectural openness actually supports meaningful autonomy.
Proven infrastructure supports long-term sovereignty
Sovereign AI simultaneously supports and depends on an organization’s ability to maintain control as deployment expands. That makes infrastructure maturity and long-term availability important considerations: a proven platform can reduce risk, simplify integration, and give enterprises a clearer path to additional capacity without introducing new dependencies as requirements evolve.
Production AI, however, relies on more than silicon. Operating systems, storage, networking, memory, management, and cooling all have to work together to support reliable deployment, operation, and expansion at scale. For enterprises, the broader ecosystem can shorten the path from evaluating a processor to running AI workloads on infrastructure they control.
Supply continuity provides another benefit: sovereign AI deployments can expand significantly over time, making future access to equipment part of the initial architecture decision. With greater operational control, organizations can integrate the technology into existing environments, scale capacity alongside workloads, and preserve their infrastructure investments over time.
AI sovereignty enables controlled scalability
The AI stack is already absorbing unprecedented institutional knowledge, decision-making and computing activity. As AI becomes more deeply integrated into institutional operations and agents handle increasingly complex workflows, controlling the infrastructure beneath it will become critical.
Sovereignty gives organizations a way to retain that authority: where workloads run, which models they use, how systems evolve, and how much capacity they add. This dynamic fundamentally changes the role of AI infrastructure. Decisions about compute, software, models, and supply directly affect how much control organizations retain over their AI operations.
An architecture designed around internal requirements can give teams greater freedom to adopt new capabilities, adjust resources as workloads develop, and make technology choices according to their priorities. That flexibility becomes more valuable as AI moves from discrete applications into workflows that organizations rely on for essential operational functions.
The benefits compound over time, enabling enterprises to advance without forfeiting the control they worked to establish in the first place.
Contrail AIX translates these principles into infrastructure enterprises can deploy. Specifically built for AI environments, the platform combines compute, networking, storage, and the supporting software stack into an integrated and scalable system, enabling organizations to own their intelligence.
After Yotta Pitch, VEIR Raises $110M for Superconducting Power
VEIR closed an oversubscribed $110 million Series C round to move its superconducting power delivery systems for AI data centers from technology validation to commercial deployment and scaled manufacturing.
The Woburn, Mass., company will use the capital to expand manufacturing capacity, advance its product portfolio and build the technical and commercial capabilities needed to support adoption at scale. It expects its first commercial deployments in 2027.
Matter Venture Partners and Tyche Partners co-led the round, joined by LG Technology Ventures, Gates Frontier, Sabanci Climate Ventures and Hui Capital. Existing investors including Engine Ventures and Congruent Ventures also participated. VEIR has now raised $225 million in total.
VEIR’s systems pair superconducting cables with cryogenic cooling, controls, termination units and monitoring. These systems move significantly more power through a smaller physical footprint and reduce labor costs, material requirements and installation complexity. VEIR has demonstrated a 3-megawatt system and is working with customers and industry partners on AI-factory reference designs.
“This financing gives us the resources to move from demonstrating the potential of superconducting power delivery to manufacturing and deploying systems at commercial scale,” said Tim Heidel, CEO of VEIR, in a press release.
On Sept. 28, I judged the Energy category of Yotta 2026’s Innovate Arena in Las Vegas, where Tim Carr, VEIR’s senior director of business development, pitched a cable that carries the same power as a copper cable tray in a conductor one-tenth the size.
I was delighted to see VEIR on the Innovate Arena stage at Yotta and to see this round announced so soon after.
TechArena Take
Yotta 2026 put power generation at the center of the AI buildout conversation. VEIR is working on delivery, where copper requires more labor, material and space as campuses grow. This round gives VEIR the capital to prove its systems in commercial deployments. We’ll be watching for its first installations.
How io.net Rewrites the Economics of AI Compute for Startups
AI infrastructure contracts with hyperscalers can come with terms that are hard for smaller AI startups to navigate. On a recent podcast, I sat down with Ilkhom Sidikov, who works on the neocloud io.net’s IO Intelligence platform, to talk about how decentralized GPU networks are competing with hyperscalers by offering flexible, affordable options to AI innovators.
From Web3 Roots to an OpenRouter Listing
Ilkhom joined io.net in early 2024, not long after the company began turning a decentralized GPU network into something usable for AI startups and developers, an effort Ilkhom said got its start “in the age of Web3 and AI.”
He first worked on network infrastructure, and since 2025, his main project has been IO Intelligence, the vertical where io.net builds applications for AI startups, including model training, model inference, and video and image generation.
One recent milestone was being listed on OpenRouter, the LLM gateway many developers know. Io.net’s GPU network now hosts open-source models handling 2 billion to 5 billion tokens a day for OpenRouter.
Where Neoclouds Offer More Flexibility
Ilkhom said hyperscalers typically lock customers into one- to three-year contracts calibrated to protect their own margins, agreements that can be “really hard” on engineers and small AI startups. Under such contracts, a customer can end up paying for GPUs, like older 4090s, that fall behind newer architectures before the term ends. Even the AI grants that hyperscalers sometimes offer, he added, come with a catch. They typically require running on that provider’s own infrastructure.
Neoclouds, Ilkhom said, offer more room to negotiate, and io.net itself supports pay-as-you-go pricing for both GPU rental and LLM inference. Io.net’s specific advantage is how it negotiates use periods. Customers can rent a cluster for as little as 10 or 12 hours, and once they’re done, io.net shifts those same GPUs into its LLM inference infrastructure rather than leaving them idle.
“We never lose money on the idle GPUs,” Ilkhom said, adding that an idle GPU costs the same to run as one fully in use. That constant reallocation is what lets io.net offer clusters at a fraction of hyperscaler pricing.
Earning Enterprise Trust
Enterprise teams bring healthy skepticism to decentralized compute, particularly around reliability and security. Ilkhom said io.net encountered fraudsters early on who would alter a GPU’s metadata to make a cheaper card, like a 4090, pass as a far pricier H100.
Io.net’s fix was building software that profiles every hosted GPU on an hourly basis, checking whether each card meets performance benchmarks for what it claims to be.
On the network side, io.net connects nodes through virtual private networks (VPNs) to secure data in transit. It recently added a confidential inference feature that lets enterprise clients verify that every token generated, from the GPU level through the gateway to the back-end application, happens inside a secured environment.
Engineering for Scale and Profit
Running inference profitably at scale comes down to a handful of techniques, Ilkhom said: quantizing models down to formats like FP8 or INT4, using key-value (KV) caching to speed up throughput, and batching inference requests. Skip those optimizations, he said, and providers selling API tokens can end up burning cash, since deploying a raw model with default settings can make it hard to even break even.
Agents Raise New Demands
The rise of AI agents presents new demands on compute and data. Context windows have grown enormous, Ilkhom said, citing Anthropic’s own claim that nothing stops the company from building a model with a million-token context size. Combined with the development of MCP servers and skills that let agents pull real-time data instead of relying on static databases or vector search, agents now behave less like single inference calls and more like systems that maintain memory and reach out for information as they need it.
The TechArena Take
My conversation with Ilkhom conversation showed how decentralized providers like io.net are winning through an intensive focus on optimizing their resources. Io.net does this by keeping GPUs constantly busy rather than allowing them to sit idle between contracts.
Every technique he described, from shifting idle clusters into LLM inference to quantizing models, squeezes more usable compute out of the same hardware hyperscalers rely on too. Hourly hardware benchmarking helps build the trust enterprise customers need before relying on that hardware at all.
Ilkhom’s 5-year outlook does not predict that decentralized compute will displace the hyperscalers. After all, regulated and well-capitalized buyers have reasons beyond price to stay where they are. What his outlook does suggest is a market potentially splitting by workload, with contract-scale commitments on one side and short-duration, price-driven capacity on the other. For technology leaders, this opens up new possibilities to start matching each workload to the economics that fit it.
To learn more, visit io.net.
etalytics Counts the Energy Its AI Saves Every Day
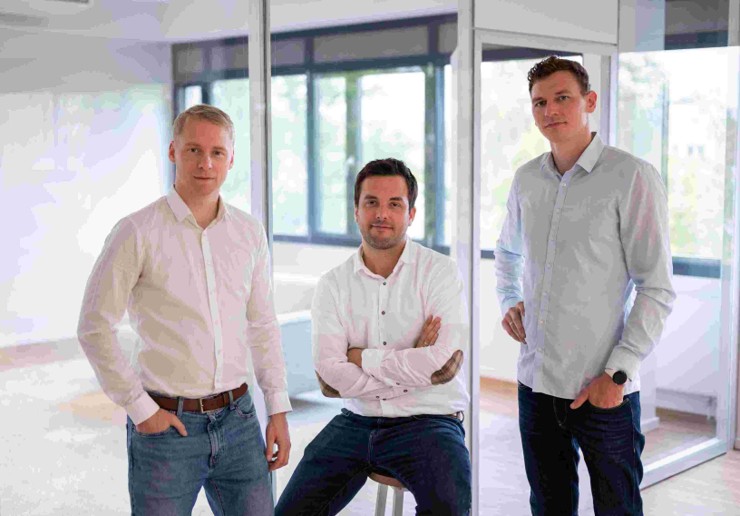
Niklas Panten and his team at etalytics keep track of how much energy their software saves per customer and site across global deployments. Watching the numbers climb unifies the team around the company’s purpose, Panten said.
Founded in 2020 as a spinoff of Niklas’ PhD research at the Technical University of Darmstadt, etalytics builds AI software that orchestrates the cooling, heating and power systems in data centers and factories so they use less energy.
The ETA Factory
Panten, co-founder and CEO of etalytics, built his PhD on a mix of mechanical engineering, computer science and energy science. He helped develop the ETA Factory, a full-scale research factory TU Darmstadt opened in 2016 to test energy efficiency on working production lines.
His research group spent more than 10 years analyzing and optimizing energy systems in manufacturing plants. Its partners included Bosch, Volkswagen and Mercedes, along with chemical and pharmaceutical companies. The researchers used AI to run cooling, heating, ventilation, on-site generation and batteries more efficiently, work Panten said began before the AI boom.
“In our research, we found almost 50% in savings in those systems,” he said.
Two research projects at the factory, PHI-Factory and SynErgie, ran from 2014 to 2018 and produced the first ideas and prototypes of etaONE, the platform etalytics sells today, according to the company. Thomas Weber, who co-founded etalytics with Panten and is now its chief strategy officer, worked on his PhD in the same lab. The founding team, which includes CTO Björn König, came together in 2019.
“(This work) came from personal passion; I was a controls engineer and I started on power converters,” he said. “I found out that we can… make (power converters) much more efficient. But even if you have the most efficient power converter, if you have the component that has a power converter in there, and it’s not operating efficiently, you’re still losing energy.”
The same problem repeated one level up. “And then looking at the component, you can optimize the component, but if it’s not optimized or orchestrated in the system, then you’re still losing energy,” he said.
That finding is the basis of etalytics: to run at its most efficient point, a whole system has to be orchestrated. In a data center, Panten applies it to cooling “from the rooftop to the server room.”
From Factories to Data Centers
In 2020, Equinix asked the team to take its approach to data centers.
“They basically asked us, ‘Hey guys, we’ve seen your potential here, can you transfer this to data centers?’” Panten said.
At Equinix’s FR6 data center in Frankfurt, etaONE cut the energy used for cooling by 900 MWh a year and avoided 240 tonnes of CO₂ emissions a year, with a payback of less than 12 months, according to etalytics.
The company kept its industrial work. At Merck’s headquarters in Darmstadt, etaONE cut the electricity used for cooling by an average of 21%, in a project coordinated by TU Darmstadt’s ETA research group. At the Stellantis paintshop in Rüsselsheim, Germany, it cut ventilation energy use by more than 60%, in a project with the university.
“Cooling is a cross-sectional technology,” Panten said. “So, the same cooling equipment that we deploy for data centers, you will find in automotive, chemical, pharma, logistics, especially cold logistics, food processing.”
Proof at Telehouse
The company’s etaONE platform sits on top of a data center’s building management system (BMS). It streams the cooling plant’s telemetry into a physics-based digital twin of the equipment, calculates new set points every two to three minutes and writes them back to the BMS.
“We don’t rip and replace anything, we just add on top,” Panten said.
At Telehouse’s Frankfurt campus, digital twins of the cooling towers showed their performance declining. etalytics traced the decline to fouling, a buildup of deposits on the towers’ heat exchangers that reduces how well they shed heat. A heat wave was approaching, and Telehouse moved its maintenance up. Panten said the predictive maintenance product grew out of checking etalytics’ own models against the plant.
“As soon as we saw deviation, we knew it’s not our models that deviate, it’s the physics that change,” he said.
Over an assessment from April 14 to Aug. 5, 2026, etaONE adjusted the cooling tower outlet temperature and the recooling pump flow. One unit used 10.4% less electricity, and etalytics projects 497 MWh in annual savings across five units. The project won the Infrastructure Sustainability Award at the Platform Global Awards 2026.
Panten said etalytics chose physics-based models over reinforcement learning so operators know why the system makes each change.
Megawatts for Compute
Panten said energy efficiency is crucial in an industry constrained by power.
“Everyone is looking for more megawatts, so when you make megawatts available from cooling, you can put them in compute,” he said.
He pointed to research from the International Energy Agency, which projects that well-documented AI use cases could save more than 13 exajoules of energy by 2035, equivalent to 3% of global final energy consumption, if barriers to wider adoption are overcome.
Looking Ahead
etalytics opened an office in the San Francisco Bay Area in May 2026, and Panten is now based in Menlo Park, California.
Microsoft’s venture fund, M12, led an investment in etalytics in 2025. This year was the company’s first time attending Yotta, and Panten said it will have a booth next year. In October, the company plans to launch etaONE IQ, an assistant for operators’ daily work, at an event with Microsoft and NVIDIA during San Francisco Tech Week. Panten said etalytics’ AI will also move onto the coolant distribution units that serve AI factories.
TechArena Take
We see cooling orchestration as one of the fastest ways for operators to free megawatts for compute without waiting on the grid. The physics-based approach matters as much as the savings, because operators of mission-critical sites need to understand every change an AI makes before they trust it.